# Dipkumar Patel — dipkumar.dev (full content)
> Full markdown content of every published post and note on https://dipkumar.dev.
# Wordmaze: a one-shot, verifier-graded puzzle for RL
> Wordmaze is a single-turn word-ladder puzzle with a password constraint, built to be trivially gradable for RL.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/llm/wordmaze/
- Published: 2026-06-03
- Updated: 2026-06-04
- Tags: llm, rl, grpo, reasoning, dataset
---
I wanted an RL task I could grade with a plain Python function [1]Lambert et al. (2024) · Tülu 3 (RLVR) · arXiv:2411.15124: no judge model, no human labels. Something a frontier model finds easy and a small one finds hard, so the gap between them is what RL has to close. Wordle is the usual pick, but it drags along multi-turn state and a reward surface that's easy to hack [2]Amodei et al. (2016) · Concrete Problems in AI Safety · arXiv:1606.06565. So I built a different one.
Numbers first. On the hard config, `gemini-3.1-pro-preview` solves **99.5%** of these puzzles. `gemini-2.5-flash` gets **36.5%**, and it burns a median of **19,374** reasoning tokens per puzzle to do it, about five times what 3.1-pro spends to win. `Qwen3.5-9B` lands at 9.5%, `Qwen3.5-4B` at 2.5%. So the task is cheap to write down, cheap to grade, and it pulls models apart. That's what you want from an RL environment.
This post is about the environment: the puzzle, the verifier, how I generate the data, and what the baselines say. The training story, what happens when you actually point GRPO [3]Shao et al. (2024) · DeepSeekMath (GRPO) · arXiv:2402.03300[4]DeepSeek-AI (2025) · DeepSeek-R1 · arXiv:2501.12948 at it, is a separate post.
## The puzzle
You get a **start** word and a **goal** word of the same length. Build a path between them under three rules:
1. Change **exactly one letter** per move.
2. Every word in the path must be a valid English word of that length.
3. Reach the goal in at most `max_moves` moves.
That much is a classic word ladder. The twist is a fourth rule, the **password**:
> For each move, look at the letter that changed. If it moved **forward** in the alphabet (`a → z`), write `F`. If it moved **backward** (`z → a`), write `B`. Concatenate those into a string. It must equal the puzzle's password.
So the path isn't just any route from start to goal. It's a route whose *shape* (the forward/backward pattern of its letter changes) spells a specific string. Here's the canonical example, `cold → warm` with password `FFBF`:
```text
cold -> cord -> word -> ward -> warm
F F B F
```
`l→r` forward, `c→w` forward, `o→a` backward, `d→m` forward: `FFBF`.
The model sees the puzzle as plain text and must reply with only the path, inside a tag:
```text
start: cold
goal: warm
word_length: 4
max_moves: 4
password: FFBF
```
```xml
cold -> cord -> word -> ward -> warm
```
That output contract is deliberate. Parsing `...` and splitting on ` -> ` is all a verifier needs: no free-text to interpret, no second model in the loop.
One dataset row (JSON)
Each row also carries a ready-to-use prompt and chat messages (system + user), so you can evaluate or train without assembling anything.
## Design choices
My goal was to build a task such that i could run RL on it with limited compute, and it can't be easily cheated through.
**Single turn, not a multi-turn dialogue.** Wordle is a multi-turn game: the model guesses, gets feedback, guesses again, and the prompt accumulates state. Now, during RL, you can still treat it as single turn, by giving previous guesses as part of the prompt. But, Reward isn't very clear in this setting. Wordmaze is designed to be a single shot. The model reads a fixed prompt and emits a complete answer. Everything the verifier needs is in that one string, which keeps rollout cost low and grading simple. So, i don't end up spending my savings on RL training.
**A constraint the model can't bluff past.** The password is the point. Without it, a word ladder has many valid solutions and a model can stumble into any one of them. Even with password, there are still many valid solutions, but at least the model has to plan. The password forces planning: you have to find a path whose letter-change directions spell a specific pattern, so most valid ladders are wrong answers. It also makes the task *character-level*. To get the password right you have to know which letter changed between two words and whether it went up or down the alphabet.
There are lot of knobs that can be tuned when you generate the dataset. For example, Password length (number of moves), Word length, Vocabulary size, etc. This knobs can be tuned to generate different difficulty levels of the task. We will talk about this in more detail in the later sections.
## The verifier
Grading is a pure function. Extract the path from `...`, split on ` -> `, and run a fixed list of checks. There are no learned components and no partial-credit heuristics baked into the truth label. Every check is a boolean:
| Check | Passes when |
|---|---|
| `valid_format` | parses to ≥2 same-length words |
| `starts_correctly` | first word == start |
| `reaches_goal` | last word == goal |
| `within_max_moves` | ≤ `max_moves` steps |
| `exact_moves` | exactly `max_moves` steps |
| `one_letter_changes` | each step changes one letter |
| `all_valid_words` | every word in the dictionary |
| `correct_word_length` | every word the right length |
| `password_matches` | computed F/B == password |
| `fully_valid` | all of the above |
`fully_valid` is the metric we care about in the evaluation. The per-check booleans are what make the dataset useful for RL: instead of a sparse 0/1 signal, you have multiple booleans which can be used to shape a overall reward.
**`at most` versus `exactly`.** The prompt asks the model to reach the goal "in at most `max_moves` moves," but the verifier tracks both `within_max_moves` and `exact_moves`. That difference matters. If the reward only says "valid path that reaches the goal," a model can learn the shortcut: emit a two-word answer like `cold -> warm`, pass the loose checks, and ignore the password. More on that in the training post. For now, this is why the verifier reports both checks.
Here's the verifier as a toy. The start and goal are fixed; fill the blanks between them, one word per step, and watch every check resolve as you go:
fill the ladder in moves · password
Build a word ladder: change exactly one letter each step to get from the first word to the last, in the number of moves shown. For each step, F means the changed letter moved forward in the alphabet and B means backward; the F/B string has to spell the password.
Type each step one letter per box; it auto-advances. The changed letter lights up green; the box turns red if the step isn't a valid one-letter word. The F/B under each arrow builds the password. Words are checked against a wordfreq English list, loaded in the background.
password
The widget checks each word against a wordfreq English list (the common 4- and 5-letter words), fetched on demand. The grader is a touch more lenient: it accepts any word wordfreq has frequency data for, so an obscure word the widget rejects might still pass there.
## Generating the dataset
Puzzles are built backwards, the way a mystery writer starts with the culprit and works back to the clues. This is how your favourite murder mystery novel was written probably.
Start with a solution path, then read the constraints off it. The generator ([`create_dataset.py`](https://huggingface.co/datasets/immortal3/wordmaze/blob/main/create_dataset.py)) does this:
1. **Vocabulary.** Take the top 10,000 English words by frequency (via `wordfreq`), keep only pure `[a-z]` strings, and drop proper nouns: a blocklist of countries, major cities, US states, plus first names from NLTK. Common words keep the puzzles readable and keep the neighbor graph dense.
2. **Neighbor graph.** For each word length, build a graph where words are nodes and an edge connects two words that differ in exactly one position. The trick is bucketing by wildcard pattern (`c*ld`, `co*d`, …) so you find neighbors in linear passes instead of comparing every pair. There are many ways to do this and honestly, this is itself a leetcode coding interview question.
3. **Random walks.** Sample simple paths (no repeated words) of the requested length, then read off the start, goal, and password from each path. Because the password is *derived* from the walk, every generated puzzle is solvable by construction.
4. **Dedup and split.** Drop duplicates keyed on `(start, goal, password, length, moves)`, shuffle, assign stable IDs, and split 80/10/10 into train/validation/test.
A few notes to keep in mind.
- Six-letter graphs are sparse, so random walks dead-end far more often than four-letter ones, and the generator logs thousands of failed attempts to fill the longer buckets.
- Your sampled `path` is not the *only* solution, a model that finds a different valid path is still correct, which is why you grade with the verifier and never string-match against the reference.
- Verifier has different dictionary than our dataset generation script, in dataset generation, we only use top 10k words by frequency, but the verifier uses the entire wordfreq English list.
Two configs are released, both 2,000 puzzles split 1,600 / 200 / 200:
- **`m3-4`**: 4-6 letter words, 3-4 moves. The easier curriculum config.
- **`m4-6`**: 4-6 letter words, 4-6 moves. The harder one, and the default.
Both live on the Hub at [`immortal3/wordmaze`](https://huggingface.co/datasets/immortal3/wordmaze), together with the generator script. It's self-contained (dependencies declared inline), so `uv run` builds the environment on the fly. Regenerate `m4-6` with:
```bash
uv run create_dataset.py \
--move-counts 4-6 --word-lengths 4-6 \
--num-examples 2000 --seed 42
```
## Baselines
This is the most fun part, also where you lose money if you don't have free credits.
Here is the baseline on the hard `m4-6` test split:

The top models basically solve it: 3.1-pro at 99.5%, 3.5-flash at 83.5%. The small open models are stuck in single digits, 9.5% for the 9B and 2.5% for the 4B. That gap, near-perfect at the top and almost nothing at the bottom, is the whole reason I made the dataset.
Accuracy alone hides the more interesting part, though. Here it is plotted against how much each model thinks (its reasoning tokens):

Look at the weakest of the three. `gemini-2.5-flash` scores 36.5%, and not because it ran out of room to think. The opposite. It uses a median of 19,374 reasoning tokens [5]Wei et al. (2022) · Chain-of-Thought Prompting · arXiv:2201.11903 per puzzle, against 3.1-pro's 4,100, and still loses. On six-move puzzles its median goes past 60k. In the plot, the dot is each model's median and the diamond is its slow tail (the 95th percentile). Both flash models hit the 63k token cap on their worst puzzles; 3.1-pro's worst (about 10k) is still below 2.5-flash's typical puzzle. So 2.5-flash isn't really reasoning, it's flailing: it searches, second-guesses, and never lands. **More thinking time isn't the fix. A better model is.** [6]Snell et al. (2024) · Scaling LLM Test-Time Compute · arXiv:2408.03314 The stronger model gets there with less thinking, not more.
Where do the failures concentrate? Format and word-validity are nearly free for everyone. Even 2.5-flash gets 98% valid format and 80% valid words. The puzzle lives in two checks: `one_letter_changes` and `password_matches`. 2.5-flash matches the password only 44% of the time. The character-level bookkeeping, which letter changed and in which direction, is what separates the models.
The open models fail the same way, only harder. Stripped of a reasoning budget the 4B collapses toward zero, 4% on `one_letter_changes` in direct-answer mode. A concrete 4B failure, on a four-move puzzle:
```text
stark -> shark -> shore -> shire -> share
```
Every word is real. But `shark -> shore` changes two letters, not one, so the path is not a valid ladder and the password can't even be computed. The model produced plausible English and quietly broke the rule that makes it track characters.
## Difficulty as a dial: m3-4 vs m4-6
Everything above is the hard config. Wordmaze also ships an easier one, and together they form a clean difficulty ladder: m3-4 is 3-4 moves, m4-6 is 4-6, same vocabulary and rules, just more steps to plan and a longer password to satisfy. Running the full frontier sweep on both turns the difficulty knob and shows who actually holds up.
| model | m3-4 (3-4 moves) | m4-6 (4-6 moves) |
|---|---|---|
| gemini-3.1-pro-preview | 99.5% | 99.5% |
| gemini-3.5-flash | 95.5% | 83.5% |
| gemini-2.5-flash | 56.5% | 36.5% |
| Qwen3.5-9B (open) | 32.5% | 9.5% |
| Qwen3.5-4B (open) | 18.5% | 2.5% |
The strongest model barely notices: 3.1-pro is 99.5% on both configs. The weaker ones drop as puzzles get longer, and 2.5-flash drops the most. But the two averages hide what's really going on. It's clearer move by move.

The chart plots accuracy and thinking against the number of moves, one line per config. The two lines meet at four moves, which tells us the difficulty comes from how many moves a puzzle needs, not from which config it came from. That's the dial I lean on in the training post. 3.1-pro stays flat near 100% from three moves to six, and its thinking only creeps up, about 1.4k tokens to 5.7k. 2.5-flash goes the other way on both: accuracy falls from 65% to 17%, and its thinking jumps from 6k to 63k on the six-move puzzles. Ten times the effort, a sixth of the wins. Harder puzzles should cost more thought, sure, but for a good model that cost stays small, and for a weak one it blows up [7]Shojaee et al. (2025) · The Illusion of Thinking · arXiv:2506.06941.
Mean versus median says the same thing more sharply. For 3.1-pro the two are close (on m4-6, median 4.1k, mean 4.7k), so almost every puzzle costs about the same. For 2.5-flash the mean sits well above the median (median 19k, mean 31k; on m3-4 the mean is triple the median). That gap means a handful of puzzles send it spiraling into tens of thousands of tokens with nothing to show. 3.5-flash has those bad puzzles too, but it usually still gets the answer. 2.5-flash usually doesn't.
Wall-clock time tells the same story. On the m3-4 runs I also logged how long each request took. At the median, 3.5-flash is fastest (12s), 3.1-pro a bit slower at 19s (bigger model, fewer tokens), and 2.5-flash slowest at 33s. The tail is where it hurts: 3.1-pro and 3.5-flash stay under about 40 seconds 90% of the time, but 2.5-flash's slowest 10% run over four minutes. Its average is 92 seconds, nearly triple its median, the same runaway tail, now in seconds instead of tokens. The best model isn't the quickest per puzzle, but it's the only one you'd trust on a deadline.
The open models ride the same ladder, one tier down (the bottom two rows above): they slide with difficulty exactly like the flash models, only starting far lower.
## The tokenization barrier
Remember the two checks every model flunked: `one_letter_changes` and `password_matches`. Both are about letters, and that turns out to be the whole problem.
Here's a real answer from gemini-2.5-flash:
```text
chips -> ships -> shops -> shots -> steps
```
It reads like a clean ladder. But look at the last step. `shots -> steps` changes three letters at once (h→t, o→e, t→p), not one. The model wrote it down anyway. To you the mistake is obvious, you just look at the spelling. The model can't look at the spelling that easily, and that's the catch.
A language model doesn't read letters, it reads tokens [8]Sennrich et al. (2016) · Subword Units (BPE) · arXiv:1508.07909. A short word like `shots` or `steps` is usually a single token, one number to the model. And those two numbers are unrelated: nothing in them tells the model which letters the words share or where they differ. So to answer "did exactly one letter change?", the model can't just glance at the spelling. It has to recall each word letter by letter, line the two up, and compare, all in its head, in words.
The password is harder still. For every move the model has to find which letter changed *and* decide whether it moved forward or backward in the alphabet (`l → r` is forward, so `F`). That's two small character puzzles per step, on top of searching for a valid path. Frontier models grind through it with thousands of tokens of scratch work. A 4B can't keep that up, so it falls apart.
So here's a test. If the tokenizer is the problem, handing the model the letters should help. I reran the 4B with every word spelled out with spaces, `c o l d` instead of `cold`. Now each letter is its own token, which is the idea behind character-level models [9]Xue et al. (2021) · ByT5 · arXiv:2105.13626[10]Clark et al. (2021) · CANINE · arXiv:2103.06874:

It worked. One-letter steps doubled, password matches nearly doubled, and fully-valid went from 18.5% to 26.5%, even though spacing makes the text about twice as long, so the model has *less* room to work, not more. Handing it the letters helped more than the extra length hurt. That's a strong hint the tokenizer, not raw smarts, is a real part of why small models struggle here.
## What's next
That's the environment: a one-shot puzzle, a pure-function verifier with a per-check signal, a reproducible generator, and a baseline gap that runs from 99.5% at the frontier down to single digits for a 4B. The gap is the whole motivation. A small open model can *almost* do this when you give it room to reason, which is the regime where RL might help: there's a non-zero success rate to amplify.
The next post is the training story: what happens when you point GRPO at a 4B and try to close that gap. It does not go the way you'd hope. The first honest result is that a naive pipeline made the model *worse* than its untrained base, by learning to game the very checks above. That failure, what it says about reward design, and whether RL can push a model past what its base already does [11]Yue et al. (2025) · Limits of RLVR · arXiv:2504.13837, is part two.
The dataset is on the [Hub](https://huggingface.co/datasets/immortal3/wordmaze) if you want to point a model at it. If you beat 3.1-pro, I'd like to know how.
## References
Tülu 3: Pushing Frontiers in Open Language Model Post-Training. Lambert et al. (2024). Introduces RLVR (RL from verifiable rewards). arXiv:2411.15124
Concrete Problems in AI Safety. Amodei et al. (2016). On reward hacking and specification gaming. arXiv:1606.06565
DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. Shao et al. (2024). Introduces Group Relative Policy Optimization (GRPO). arXiv:2402.03300
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. DeepSeek-AI (2025). arXiv:2501.12948
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. Wei et al. (2022). arXiv:2201.11903
Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters. Snell et al. (2024). arXiv:2408.03314
The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity. Shojaee et al. (2025). Reasoning models vs puzzle complexity. arXiv:2506.06941
Neural Machine Translation of Rare Words with Subword Units. Sennrich et al. (2016). Byte-pair encoding. arXiv:1508.07909
ByT5: Towards a Token-Free Future with Pre-trained Byte-to-Byte Models. Xue et al. (2021). arXiv:2105.13626
CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation. Clark et al. (2021). arXiv:2103.06874
Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model?. Yue et al. (2025). arXiv:2504.13837
---
# Claude Managed Agents: sharp edges and gotchas
> What Anthropic Claude Managed Agents provide, where the API is limited, and gotchas around sessions, environments, tools, and GitHub repos.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/agents/claude-managed-agents-gotchas/
- Published: 2026-04-26
- Updated: 2026-06-17
- Tags: agents, claude, anthropic
---
## What Are Managed Agents?
Anthropic released [Managed Agents](https://docs.anthropic.com/en/docs/agents/overview) in April 2026. The idea is simple: instead of building your own agent loop, tool execution sandbox, and session persistence, Anthropic hosts all of it for you.
You define an **Agent** (model + system prompt + tools), create an **Environment** (a sandboxed Ubuntu container), and spin up **Sessions** that run your agent against real tasks. The interaction is event-driven over SSE. You send user messages in, you get agent actions out. Anthropic runs the loop, manages the container, handles compaction, and persists the session history.
The four core primitives:
| Concept | What it is |
| --------------- | -------------------------------------------------------------------------------------------------------------------------- |
| **Agent** | A reusable, versioned configuration: model, system prompt, tools, MCP servers, skills. Create once, reuse across sessions. |
| **Environment** | Container template: networking rules, pre-installed packages. Ubuntu 22.04, up to 8 GB RAM, 10 GB disk. |
| **Session** | A running agent instance. Gets its own isolated container. Stateful, persistent event history. |
| **Events** | The interaction protocol. SSE streaming or polling. No webhooks. |
It's a good product direction. But it's also a beta, and betas come with sharp edges. If you are evaluating this for production, here are the things that will bite you.
## 1. Custom Tools Require an Active Event Loop
This was the first thing that surprised me. Custom tools, the ones where *your* application executes the logic instead of the agent's sandbox, don't work like fire-and-forget callbacks.
The flow looks like this:
1. You define a custom tool on the agent with a name, description, and input schema.
2. The agent decides to call it and emits an `agent.custom_tool_use` event.
3. The entire session goes **idle** and waits.
4. Your application reads the event, executes the tool, and sends back a `user.custom_tool_result` event.
5. The session resumes.
There is no webhook. There is no callback URL you register. Your application must hold an SSE connection open (or poll `events.list`) to detect when the agent wants something from you. If your SSE stream drops while a custom tool call is pending, the session deadlocks. You need to implement reconnect-with-consolidation: open a new stream, fetch full history via `events.list`, dedupe by event ID, then resume.
So, you can't just define a tool and walk away. You need an always-on listener. For teams used to webhook-driven architectures, this is a meaningful shift in how you design your integration layer.
The alternative? Move your tools to an MCP server. MCP tools execute server-side and don't require your application to stay connected. But that introduces its own complexity.
## 2. MCP Is the Escape Hatch, but It Has Its Own Friction
If custom tools feel heavy because of the event loop requirement, Anthropic's answer is MCP (Model Context Protocol) servers. MCP tools run remotely and the agent calls them directly, no client-side listener needed.
But MCP integration is not as plug-and-play as it sounds:
- **Only remote MCP servers with Streamable HTTP transport are supported.** No local stdio-based servers. If you have been building MCP servers locally for Claude Desktop or Claude Code, they won't work here without a transport adapter.
- **Credential setup is not trivial.** Vaults support two auth types: `mcp_oauth` (with refresh flows) and `static_bearer` (for fixed API keys or PATs). The `static_bearer` path is simpler, but not every MCP server accepts it. For OAuth-based servers, you need proper token endpoints, client IDs, and refresh logic configured in the [Vault credential](https://platform.claude.com/docs/en/managed-agents/vaults). Either way, you are managing credentials through Anthropic's Vault abstraction rather than passing them directly.
- **Vault credentials never enter the sandbox.** They are injected by [Anthropic-side proxies](https://www.anthropic.com/engineering/managed-agents) after requests leave the container. Claude calls MCP tools via a dedicated proxy that resolves credentials from the vault and makes the external call. The harness itself is never made aware of any credentials. This is good for security, but it means you can't reuse vaulted secrets for non-MCP purposes inside the container. If you need an API key for a shell command, you need a separate path.
- **Max 20 MCP servers per agent, 128 tools total across all types.**
MCP is clearly the intended long-term path for external integrations. But the Vault-mediated credential model and the remote-only transport constraint mean you will spend time adapting existing tools.
## 3. No Webhooks. SSE or Nothing.
This deserves its own section because it affects the architecture of every integration you build.
There is no webhook support. Communication with a running session happens through two channels:
- **SSE streaming** (`GET /v1/sessions/{id}/events/stream`): a long-lived connection that delivers events in real time. This is the primary interface.
- **Polling** (`GET /v1/sessions/{id}/events`): paginated event list. Returns immediately. Useful for backfill, not for real-time.
The SSE stream has no replay. If your connection drops, you miss events. You must implement reconnect-with-consolidation every time. You also need to open the stream *before* sending your first event, because the stream only delivers events emitted after it opens. This one is easy to miss.
There are a few subtle timing issues too:
- **Don't break on bare `session.status_idle`.** The session goes idle transiently for tool confirmations and custom tool calls. Only break when idle with `stop_reason.type === "end_turn"` or `"retries_exhausted"`, or on `session.status_terminated`.
- **Post-idle status-write race.** The SSE stream emits `session.status_idle` slightly before the queryable status reflects it. If you immediately call `sessions.delete()`, it can 400.
- **HTTP library timeouts are per-chunk, not wall-clock.** A standard `requests timeout=(5, 60)` can block indefinitely on a trickling SSE response. Use the SDK or track elapsed time yourself.
For any serious production use, plan to build a robust event consumer with reconnection, deduplication, and state reconciliation. This is table stakes for SSE-based systems, but it's work that Anthropic could eventually eliminate with webhook support.
## 4. File Mounting: Current Limitations
File mounting works today, and the basic mechanism is straightforward:
1. Upload via Files API: `client.beta.files.upload({ file, purpose: "agent" })`
2. Mount at session creation: `{ type: "file", file_id: "file_abc123", mount_path: "/workspace/data.csv" }`
You can also mount GitHub repositories directly, which is useful for code-review and analysis workflows. Repos are cached, so repeated sessions against the same repo start faster.
That said, the current beta has a number of constraints around files and environments. These are likely to improve as the product matures, but today they shape what you can and can't do:
- **Files are mounted read-only.** The agent reads them but can't modify originals. Modified versions go to new paths.
- **Max 100 files per session.**
- **Mounted files get a different `file_id` than the uploaded original.** Session creation makes a scoped copy. Don't assume IDs are stable across the boundary.
- **Brief indexing lag (~1-3 seconds)** between `session.status_idle` and output files appearing in `files.list`. If you check immediately, you will get an empty list.
- **Memory stores (persistent cross-session storage) can only be attached at session creation time.** You can't add them to a running session.
- **No custom container images.** `config.type: "cloud"` is the only option. You can pre-install packages in the environment definition (`apt`, `pip`, `npm`, `cargo`, `gem`, `go`), but you can't mount arbitrary Docker images with your application code pre-baked. The container starts from Anthropic's base image every time.
- **No environment variables in containers.** If your tools need config, you either bake it into the system prompt (which persists in event history) or use a custom tool pattern where your orchestrator holds the config.
Most of these feel like beta-era constraints rather than deliberate design choices. Custom container support, writable mounts, and environment variable injection are all reasonable future additions. But if you are planning around them today, plan around what exists, not what might ship.
## 5. Business Logic Is Your Problem
This is expected, but worth saying clearly: Managed Agents gives you a hosted agent runtime, not a hosted application platform.
You still need to build:
- **Agent-per-tenant routing.** The API gives you `agents.create()` and `sessions.create()`, but deciding which agent config maps to which customer, which tools a given user should have access to, and how to manage agent versions across your user base, that's entirely on you.
- **Multi-agent orchestration logic.** There is a multi-agent feature in research preview, but it only supports one level of delegation and requires a separate access request. For anything more complex, you are building the coordinator yourself.
- **YAML-driven agent definitions.** If you want to version-control agent configs (and you should), the recommended path is YAML files deployed via the `ant` CLI. But the lifecycle management, CI/CD pipeline, and rollback strategy are yours to design.
- **Cost controls and usage limits.** Sessions bill at $0.08/session-hour plus standard token rates. There is no built-in per-user spend cap. If a runaway agent loops for hours, your bill reflects that. You need to implement your own circuit breakers.
Anthropic provides Vaults for credential management and Memory Stores for cross-session persistence, which help. But the glue between "i have an agent" and "i have a product" is still a significant engineering surface.
## 6. Session History: Store Your Own Copy
Session event history is stored server-side and accessible via `events.list()`. You can retrieve the full history of any session, which is convenient.
But i would recommend also storing it in your own infrastructure. Here's why:
- **Archive is permanent.** Once you archive a session, there is no unarchive. Agents also have no delete, only archive. If you archive something by mistake, you lose write access to it forever.
- **You will want to query across sessions.** The API gives you per-session history, but no cross-session search or analytics. If you want to answer "which sessions hit a tool error last week?" or "what is the average token usage per agent type?", you need your own data store.
- **Compliance and auditing.** If you operate in a regulated industry, you likely need session logs in your own infrastructure regardless of where the runtime lives.
- **Built-in context compaction summarizes older turns.** This is great for token efficiency during a session, but it means the raw event history includes compaction events that replace earlier context. If you want the full uncompacted transcript, capture events as they stream in.
## Looking Forward
These are real limitations today, but it's worth acknowledging: this is a beta released weeks ago. Anthropic is iterating quickly, and several of these gaps have clear paths to resolution.
Webhook support would eliminate the always-on listener requirement for custom tools. Bring-your-own-container would unlock richer environment setups. Environment variable support in containers would simplify credential management for non-MCP tools. These are not architectural impossibilities. They are features that haven't shipped yet.
The core architecture is sound. Durable session logs decoupled from containers, versioned agent configs, sandboxed execution with MCP integration. The separation of "brain" (Claude + harness) from "hands" (sandbox + tools) is the right abstraction. The question is whether the edges get polished fast enough for production workloads that can't wait.
If you are building something new and can tolerate beta constraints, Managed Agents removes a meaningful amount of infrastructure work. If you are migrating an existing agent system with webhook-driven tools, custom container images, or complex multi-agent hierarchies, the current feature set will require workarounds.
Either way, know the gotchas before you commit.
---
# IndiGo: India's Affordable Growth Carrier, by the Numbers
> A beginner-friendly look at IndiGo. A live widget lets you tune three assumptions about how India flies and see what that means for IndiGo's size and market value in 5 to 10 years.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/markets/indigo-investor-view/
- Published: 2026-04-22
- Updated: 2026-04-26
- Tags: markets, india, aviation, indigo, investing
---
IndiGo is the budget airline six of every ten Indian flyers already use. India itself flies very little: roughly **one flight per person every nine years** on average, compared to one every two years in China and 2.5 flights per person every year in the US. That gap is the whole story. This post gives you a widget to play with the math first, then walks through what the numbers mean.
## The widget
Drag the sliders. The top three set how India's aviation market grows. The fourth sets how much the stock market values the resulting earnings. Hover the **?** icons for a plain-language explanation of each lever.
Defaults = a cautious base case. Use the preset buttons below to jump between cautious, middle, and aggressive views.
Presets:
How many years ahead ?The time horizon. 5 years = halfway to 2031. 10 years = 2035.
10y
India's total domestic flyers
Market growth per year (CAGR)
IndiGo's flyers
IndiGo growth per year (CAGR)
IndiGo revenue
IndiGo market cap (implied)
Starting values: India 184M domestic flyers in 2025, IndiGo 118M of them, IndiGo revenue ₹80,803 cr, profit margin 9%, market cap ₹1.79 lakh cr. Revenue per flyer held flat. Population grows linearly to 1.55B by 2035. Bars compare against Airbus's 8.9% forecast. Not investment advice.
## Why India flies so little (and why that matters)
India is a country of roughly 1.45 billion people where fewer than 200 million domestic flights happen in a year. That's the same as 0.11 flights per person. For comparison:
| Country | Flights per person per year |
|---|---|
| **India** | **0.11** |
| Indonesia | 0.35 |
| China | 0.44 |
| Brazil | 0.45 |
| United States | 2.51 |
India today sits roughly where China sat in 2008-2010. If India simply grows toward half of where China is today over the next 10 years, the domestic flyer count nearly doubles. If it matches China, it quadruples. That is the runway the widget is modeling.
Sources: [World Bank](https://data.worldbank.org/indicator/IS.AIR.PSGR), [US BTS](https://www.transtats.bts.gov/), [Wikipedia Aviation in India](https://en.wikipedia.org/wiki/Aviation_in_India).
## Why IndiGo has 60% share
IndiGo is the market leader because it survived. Jet Airways collapsed in 2019. Go First grounded in May 2023 and never came back. SpiceJet runs at 3-4% share with a broken balance sheet. Akasa is growing but still small.
What IndiGo does right, in plain terms:
- Flies one aircraft type (the Airbus A320 family) so pilots, maintenance, and spare parts are shared across the whole fleet.
- Buys aircraft cheap and leases them to finance companies who lease them right back (keeps debt light on paper).
- Holds the best time-slots at Delhi, Mumbai, Bengaluru, which smaller rivals can't profitably match.
Current share trend:
| Month | IndiGo | Air India Group | Everyone else |
|---|---|---|---|
| Aug 2025 | 64.2% | 27.3% | 8.5% |
| Dec 2025 | 59.6% | 29.6% | 10.8% |
Source: [Wikipedia Aviation in India](https://en.wikipedia.org/wiki/Aviation_in_India). The December dip is from a crisis we cover below.
## Airports: the runway is being paved
India has about **150 commercial airports operating today**. The government's target is 200+ by the early 2030s, with UDAN-backed regional airports filling the gap.
The specific numbers that matter for IndiGo:
- Today's airport capacity: roughly **350 million passengers per year** across the top metros.
- New capacity by 2027: roughly **+100 million** (Navi Mumbai opened Dec 2025, Noida-Jewar launching now, Delhi T1 rebuild done, Bengaluru T2 Phase 2 coming).
- By 2035: cumulative additions pass **+200 million** as these new airports scale to full size.
In plain English: a country that handles ~184M domestic flyers today will soon have the runways, gates, and terminals to handle 500M+ without breaking. Slot scarcity, which has been IndiGo's quiet growth ceiling, is lifting right as its fleet deliveries ramp up. IndiGo is the designated launch carrier at Jewar alongside Akasa and Air India Express.
## Where IndiGo stands right now
**The five-year picture (consolidated, ₹ cr):**
| Fiscal | Revenue | Profit |
|---|---|---|
| FY21 (pandemic) | 14,641 | (5,806) |
| FY22 | 25,931 | (6,162) |
| FY23 | 54,446 | (306) |
| FY24 | 68,904 | 8,172 |
| FY25 | 80,803 | **7,258** |
| Last 12 months to Dec-25 | 84,675 | 3,211 |
The profit collapse in the last line is recent and deserves its own paragraph.
**What happened in December 2025.** India's aviation regulator (DGCA) introduced stricter crew-duty rules effective 2 December. IndiGo was understaffed for the new rules, cancelled about 4,500 flights in ten days, lost 717 airport time-slots to competitors, and booked a one-time hit of roughly ₹1,546 cr. Profit in the October-December 2025 quarter fell to **₹549 cr** from ₹2,448 cr a year earlier. The CEO, Pieter Elbers, resigned in March 2026. [Willie Walsh](https://en.wikipedia.org/wiki/Willie_Walsh), the outgoing head of the global airline industry body IATA, takes over as CEO in August 2026.
**The fleet.** 434 aircraft in August 2025, around 440 today. On order: roughly **900 more aircraft** spread across the next decade, the largest commercial aircraft order in history.
**The valuation today (22 April 2026):**
- Share price: ₹4,641 (52-week range ₹3,895-6,232, so about 25% below the high).
- Market cap: ₹1.79 lakh cr (roughly US$19 billion).
- P/E ratio: 39x last-twelve-month earnings.
- Promoter holding: 41.6% (down from ~70% three years ago as co-founder Rakesh Gangwal's family has sold down).
A P/E of 39x is richly valued for an airline. It means the market is paying for years of future growth, not for today's earnings alone.
## What could break the thesis
- **Fuel prices**. Jet fuel is 30-40% of an airline's costs and is priced in US dollars. A sustained oil spike compresses margins fast. IndiGo doesn't hedge fuel.
- **Rupee weakness**. Aircraft leases, fuel, and some maintenance are all dollar-linked. The rupee moved from ~83 to ~93 against the dollar over eighteen months, and that alone contributed to the Q3 FY26 profit drop.
- **Slot loss overhang**. The 717 slots IndiGo gave up in December are now being redistributed. How many come back matters a lot.
- **Air India is no longer a joke**. After the Tata takeover and merger with Vistara in late 2024, Air India has 189 aircraft, 570+ on order, and billions of rupees of fresh capital from Tata Sons and Singapore Airlines. It's still loss-making but it's no longer weak.
- **International expansion is unproven**. IndiGo's long-haul widebody aircraft (the A350) start arriving in 2027. Long-haul flying is a different business from cheap domestic hops, dominated by Gulf carriers and Singapore Airlines.
- **Regulator risk**. The same DGCA that fined IndiGo and took slots away can do more. A parliamentary panel summoned the airline after the December crisis.
## What to watch
**Signs the growth story is on track**: share recovers above 60% and stays there, quarterly profit returns to pre-crisis levels by FY27, A350 deliveries land on time in 2027.
**Signs it isn't**: share drifts below 55% for a year, profit margin stays compressed from fuel or rupee weakness, Air India's domestic share crosses 35%, or the A350 program slips by more than a year.
This post is not a buy, sell, or hold recommendation. The widget lets you plug in your own assumptions and see what they imply. The story beneath the widget is about whether those assumptions are defensible. Both parts matter.
**Sources and further reading:**
- [IndiGo investor relations](https://www.goindigo.in/information/investor-relations.html)
- [DGCA monthly market share](https://www.dgca.gov.in/digigov-portal/)
- [Airbus Global Market Forecast](https://www.airbus.com/en/products-services/commercial-aircraft/global-market-forecast)
- [World Bank air transport data](https://data.worldbank.org/indicator/IS.AIR.PSGR)
All figures as of 23 April 2026 unless noted.
---
# A Practical Cost Checklist for Agent and Harness Engineering
> A staged checklist for reducing agent and LLM costs, from prompt hygiene and model selection to tool pruning, trace analysis, and distillation.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/agents/agent-harness-cost-checklist/
- Published: 2026-04-20
- Updated: 2026-04-22
- Tags: agents, harness, cost, engineering
---
## TLDR: Checklist
- [ ] **Make prompt caching actually work: stabilize the prefix and verify hit rates.**
Keep reusable system prompts and shared chat history stable so the cache has something to hit. Track hit rates, and use provider-specific cache controls when they actually improve savings.
- [ ] **Re-evaluate your default model.**
The easiest cost win is often switching to a cheaper model that still clears your quality bar on your own eval set.
- [ ] **Right-size the output: reasoning budget and visible tokens.**
Output tokens are the most expensive tokens you generate. Match both the reasoning budget and the visible response length to the task. Routing does not deserve deep thinking or a paragraph.
- [ ] **Move offline work to batch or flex lanes.**
Evals, backfills, enrichment, and asynchronous jobs should not be priced like interactive traffic.
- [ ] **Compact context mid-run.**
Long agent runs keep paying for the same tool outputs and failed turns on every subsequent call. Compaction collapses stale history into summaries so you stop re-paying for yesterday's context on today's call.
- [ ] **Fix your tools: load less, return less, regenerate less.**
Attaching every tool inflates the prompt before the agent starts. Giant payloads inflate the next call after. And for edit-heavy workflows, regenerating the whole output when most of it is unchanged wastes tokens you never needed to produce.
- [ ] **Make fewer requests and parallelize independent work.**
A lot of agent cost comes from orchestration shape: too many round trips, too many retries, and too much sequential work.
- [ ] **Collect traces and read them like a cost report.**
Without traces, you do not know where the repeated waste actually is.
- [ ] **Cap the blast radius.**
One runaway loop, retry storm, or misconfigured thinking budget can 100x a session's cost before anyone notices. Hard caps on tokens, tool calls, retries, and spend turn unbounded worst cases into bounded ones.
- [ ] **Do not default to an LLM when deterministic logic is enough.**
The cheapest token is the one you never send.
- [ ] **Turn good traces into cheaper task-specific models.**
Once the basics are clean, distillation or fine-tuning can move repeated workflows onto smaller models.
## Introduction
Once you hit a certain scale, LLM cost becomes a significant part of your overall cost. You cannot ignore it anymore.
The customer acquisition phase is over, and now you are in the growth phase. You need to know your COGS (Cost of Goods Sold) and make sure the product can stay profitable. This is a simple checklist to help with that. I have ordered it so you can start with the easy wins and then move toward the more complex work.
This is not a silver bullet, and any engineer who has worked on agent systems already knows some of these things. But it is still a good place to start.
### 1. Make prompt caching actually work: stabilize the prefix and verify hit rates
This is the first thing I would check because it is one of the highest-leverage fixes and it is often half-done.
There are really two parts here, and both matter.
**First, keep the prefix stable.** Prompt caching only works when the reusable prefix stays identical. If you keep changing the system prompt, tool order, or early context, there is nothing for the cache to hit.
Teams often destroy cacheability by accident:
- injecting the exact timestamp into the system prompt on every request, even when the current date or a coarse time window would be enough
- adding volatile session metadata high in the prompt
- changing tool definitions or tool order between turns
- stuffing retrieval output ahead of stable instructions
Caching is not magic. You also need to understand how your provider actually implements it. Some providers let you control TTL. Some need explicit cache breakpoints. Some distinguish between implicit and explicit caching. If you do not understand the mechanism, it becomes very easy to think caching is enabled while getting little value from it.
**Second, verify it is working.** A lot of teams clean up the prompt and then never look at the numbers. That means they feel better about caching without knowing whether they actually saved anything. If you already have observability in place, there is a good chance cache-hit data is available somewhere. You just have to look at it routinely.
Questions to ask:
- what is the cache-hit ratio?
- which workflows, agents, or model calls have low cache-hit ratios?
- how much latency and cost benefit are we actually getting from caching?
If you do not measure cache hits, you do not know whether this section is helping or just sounding smart.
**If you want to go deeper:**
- [OpenAI prompt caching](https://platform.openai.com/docs/guides/prompt-caching)
- [Anthropic prompt caching](https://docs.anthropic.com/en/docs/build-with-claude/prompt-caching)
- [Google Gemini context caching](https://ai.google.dev/gemini-api/docs/caching/)
### 2. Re-evaluate your default model
This is often the cheapest win because one model switch can change every request that follows.
Too many teams launch with the strongest model available, get the product working, and then never revisit the choice. That is fine in the early stage. It gets expensive later.
Be empirical, not sentimental:
- test a smaller model against your real workload
- do not trust a handful of cherry-picked prompts
- do not assume the model you launched with is still the right price/performance call
Public trackers can help you shortlist candidates, but the real answer has to come from your own eval set. A leaderboard is useful for a first pass. It should not make the final decision for you. Smaller open-source models are also getting better quickly, so they are worth considering if your workload and deployment constraints allow it.
Before building a router, before rewriting the harness, before talking about fine-tuning: if you swapped this model tomorrow, would users notice enough quality loss to justify the bill?
**If you want to go deeper:**
- [Anthropic prompt engineering](https://docs.anthropic.com/en/docs/prompt-engineering)
- [OpenAI cost optimization](https://platform.openai.com/docs/guides/cost-optimization)
- [Artificial Analysis model leaderboard](https://artificialanalysis.ai/leaderboards/models)
### 3. Right-size the output: reasoning budget and visible tokens
Most teams focus on input context and forget that output is where a lot of the bill shows up. In practice, you usually have two dials here, and both need to be controlled.
**First dial: the reasoning budget.** Not every step deserves heavy thinking. Code synthesis, planning, and ambiguous research may need it. Routing, classification, extraction, and simple transforms usually do not.
If you are using a reasoning-capable model for lightweight internal steps, there is a good chance you are overspending.
- hard planning, code synthesis, multi-hop reasoning, or ambiguous research may deserve more thinking
- routing, filtering, extraction, and straightforward transforms usually deserve less
Check your thinking budgets explicitly. If everything is set to ultra thinking by default, there is a good chance you are burning money on tasks that do not need it. Newer models do offer adaptive thinking, and that is a good start, but if you know your domain well, you should still set deliberate limits instead of delegating the whole decision to the model.
**Second dial: the visible response.** A lot of harnesses ask for much more text than the next step or the user actually needs.
- tell the model to be brief when brevity is acceptable
- cap outputs with `max_tokens` or stop conditions where the task allows it
- shorten structured output field names
- collapse verbose schemas where you can
- avoid asking for prose when a compact label or JSON field is enough
The rule is simple: match the budget to the task. If the internal step only needs a label, do not pay for hidden reasoning and a paragraph of visible prose.
**If you want to go deeper:**
- [Anthropic extended thinking](https://docs.anthropic.com/en/docs/build-with-claude/extended-thinking)
- [Google Gemini thinking](https://ai.google.dev/gemini-api/docs/thinking)
- [OpenAI latency optimization](https://platform.openai.com/docs/guides/latency-optimization)
### 4. Move offline work to batch or flex lanes
A surprising amount of agent traffic is not interactive, but many teams still price it as if a user is waiting on every request.
Nightly eval runs, enrichment pipelines, backfills, report generation, and large review jobs do not need low-latency serving. If a workflow can wait, move it to a slower and cheaper lane.
This is a clean win because it does not require better prompts, better models, or smarter agents. It usually just requires queue separation and the discipline not to mix interactive and offline traffic.
If a workflow can wait minutes or hours, it should not be priced like a user-facing request. It is also worth checking provider pricing carefully here, because discounts, batch modes, and slower compute lanes are not packaged the same way across vendors.
**If you want to go deeper:**
- [OpenAI API pricing](https://openai.com/api/pricing/)
- [OpenAI cost optimization](https://platform.openai.com/docs/guides/cost-optimization)
- [OpenAI Flex processing](https://platform.openai.com/docs/guides/flex-processing?api-mode=chat)
### 5. Compact context mid-run
Section 1 was about the stable prefix. This section is about the growing middle that keeps getting bigger during a long run. There are many ways to implement compaction, and you should choose the one that best fits your system.
Long agent runs quietly accumulate cost inside the context window itself. Every tool output, every failed attempt, and every old decision gets re-sent on later calls. That means the model keeps paying to reread things that are no longer useful.
Compaction fixes this by replacing stale history with a shorter summary while keeping the recent turns verbatim. The goal is not to remove useful context. The goal is to stop paying rent on dead context.
Practical moves:
- summarize older turns when the context crosses a token threshold
- drop stale tool outputs once their result has been consumed downstream
- keep the last few turns verbatim so the model still has recent grounding
- write durable facts to an external memory instead of re-sending them every turn
The test: pick a long session and look at the input token count on the last call. If most of it is material the model no longer needs, you are paying rent on dead context.
### 6. Fix your tools: load less, return less, regenerate less
Tools create cost before the call, during the call, and after the call. Most harnesses let all three happen without much control. And when I say tools here, I also mean MCP servers and skills. The same cost patterns apply there too.
**Load less.** Attaching the full tool catalog to every request is a token tax before the model does anything. Start with a smaller default set and load specialized tools only when they are actually needed.
- do not attach every tool to every task
- keep a small default toolset
- defer specialized tools until they are needed
- keep tool descriptions tight enough that the model does not thrash
**Return less.** In many harnesses, the expensive part is not the model alone. It is the amount of junk you keep feeding back into it. Tool calls often return full HTML when only two fields matter, giant JSON blobs when only one status matters, or verbose repeated metadata across every step.
Audit a few traces and ask:
- what is the minimum useful tool result?
- what can be summarized outside the model?
- do I need to send the full output, or only the parts that are actually useful to the model?
- can I send only the changes instead of the whole payload?
- what can be filtered, truncated, or schema-compressed safely?
If your tools return more than the next step needs, you pay twice: once to fetch the data and again to force the model to read it. This topic is deep enough for its own post, but even a basic audit here can remove a surprising amount of waste.
**Regenerate less.** For edit-heavy workflows like code assistants and document pipelines, do not regenerate the whole answer when only a small delta changed. If most of the file or response is stable, optimize for the change, not the entire output.
Also move loops, conditionals, and simple transforms into code where possible. Every repeated control-flow step you take out of prompt context is one less thing the model has to re-read.
**If you want to go deeper:**
- [Anthropic advanced tool use](https://www.anthropic.com/engineering/advanced-tool-use)
- [Anthropic token-efficient tool use](https://docs.anthropic.com/en/docs/agents-and-tools/tool-use/token-efficient-tool-use)
- [OpenAI latency optimization](https://platform.openai.com/docs/guides/latency-optimization)
- [OpenAI Predicted Outputs](https://platform.openai.com/docs/guides/predicted-outputs)
### 7. Make fewer requests and parallelize independent work
This is especially common in larger organizations, where many teams work on different parts of the same product and extra LLM steps get added over time. A lot of agent cost comes from orchestration shape, not single-call pricing.
Too many systems keep making extra requests because the flow was designed step by step and never simplified later.
Many harnesses quietly do too much:
- one call to contextualize
- one call to decide whether to retrieve
- one call to route
- one call to summarize
- one call to format the answer
Sometimes that decomposition is necessary. Often it is just habit.
Two checks to start:
- can multiple sequential LLM steps be merged into one structured response?
- can independent steps run in parallel instead of serially?
Every extra round trip adds cost, latency, and another place to fail. So this section is less about clever orchestration and more about removing unnecessary choreography.
Speculative execution can also help when one path dominates and you can afford to start likely work early. It is not always the right choice, but it is worth testing in high-volume systems.
### 8. Collect traces and read them like a cost report
If you are not storing traces, you are guessing.
Cost problems in agent systems are usually repetitive. The same failed retrieval path, the same tool loop, the same oversized context, the same retry storm, the same reasoning-heavy router call. Trace review is how you find those patterns.
At this stage, the goal is not abstract observability. The goal is operational clarity.
You want to answer questions like these:
- where are the tokens going?
- where are the repeated failures?
- which steps are low-value but high-cost?
- which prompts or tools trigger long outputs again and again?
Once you have traces, you can do something much more valuable than general optimization: targeted removal of repeated waste.
Traces also expose the worst-case shapes that the next section is built to bound.
This is also where traces become more than a debug tool. They become a decision tool. Good trace review tells you whether the real problem is retrieval quality, an oversized tool payload, an overthinking router, a retry storm, or a prompt that keeps pushing the model into unnecessary work. Once you can see that clearly, the next optimization step becomes much easier to choose.
### 9. Cap the blast radius
Every item so far is about reducing cost. This one is different: it is about bounding the *worst case*.
This section is less about saving 10 percent and more about avoiding the day you wake up to a bill that is 10x higher than expected.
Agents fail expensively when they fail. A misconfigured thinking budget, a tool that loops on itself, a retry policy with no ceiling, or a malformed structured output that keeps triggering retries can blow up the bill very quickly.
Hard caps, enforced at the harness level, are the only reliable defense. They do not need to be clever. They need to exist.
- max tokens per user turn
- max tool calls per task
- max retries per tool, not just globally
- max reasoning budget per call
- max retrieval fan-out
- max cost per user per day, with a circuit breaker that degrades gracefully
Structured outputs belong in this chapter too. Provider-native JSON mode, tool-call schemas, and grammar-constrained decoding reduce the malformed-output-to-retry loop. The main win is not shorter responses. The main win is avoiding repeated failure traffic.
This is not optimization. It is blast-radius control. Treat it like a production safety requirement, not a cost-engineering side quest.
A useful test: if a single malformed prompt triggered your agent to loop forever, how much would it cost before something stopped it? If you do not know, that is the number you are exposed to.
### 10. Do not default to an LLM when deterministic logic is enough
This is not glamorous, but it is one of the cleanest long-term cost controls.
If a step is deterministic, rule-based, or cheap to implement directly, every avoided model call is a permanent win.
Common examples:
- checking whether an order value crosses a threshold before routing to a human
- validating whether a payload matches schema before asking the model to repair it
- routing straightforward requests like password reset, pricing, or account status without an LLM in the loop
- applying guardrails and policy checks before the model ever sees the request
- returning precomputed outputs for constrained inputs instead of regenerating them every time
- rendering structured UI states directly instead of asking the model to narrate what the UI already knows
That last one matters more than it seems. Many harnesses ask the model to produce prose the user does not need. If the output is structured or predictable, render it. Do not narrate it just because a language model can.
The cheapest token is the one you never send.
### 11. Turn good traces into cheaper task-specific models
If you are still at seed stage and just trying to get the core product working, this is usually not where your time should go. This is probably the most expensive step in the checklist, and it is not for everyone.
This step comes with a real caveat: it only makes sense at a certain scale and with actual funding behind it.
The rough loop is simple:
1. get a strong prompt working on a frontier model
2. capture high-quality outputs on real tasks
3. build a dataset from those outputs
4. fine-tune or distill into a smaller model for that task
On paper that is clean. In practice, provider fine-tuning costs money upfront and requires prepaid credits or committed spend. If you are not running thousands of calls per day on the same task shape, the savings rarely justify the engineering and compute bill.
Going further and fine-tuning your own open-source 7B–20B model is a completely different game. You need GPU infrastructure, data pipelines, evaluation harnesses, and ML engineering bandwidth. Some teams get there and it pays off. Most teams are not there yet, and spending time here before the earlier steps are clean is a mistake.
The gap between "pay the provider for a closed fine-tune" and "run your own GPU cluster" has narrowed a lot. Managed APIs like Thinking Machines' Tinker, Together AI, and Fireworks now expose LoRA fine-tuning over open-weight models like Qwen, Llama, and DeepSeek while handling the distributed training infrastructure. You keep the weights, which means the resulting model is portable across inference providers. If you have GPU access and want to run it yourself, libraries like Unsloth and Hugging Face PEFT make LoRA and QLoRA tractable on modest hardware.
None of this removes the need for a real eval set, a real dataset, and real ML judgment. It just lowers the activation energy. Pair these tools with techniques like on-policy distillation when a smaller student model needs to match a larger teacher on a specific task shape.
The honest default: if you have a high-volume, stable, repeating task and enough budget to run the experiment properly, investigate it. If you do not, skip this and spend the effort on something earlier in the list.
**Define success criteria before you start.** Without a clear quality floor, distillation is just guesswork.
**If you want to go deeper:**
*Managed LoRA fine-tuning over open-weight models:*
- [Thinking Machines Tinker](https://thinkingmachines.ai/tinker/)
- [Together AI fine-tuning](https://docs.together.ai/docs/fine-tuning-overview)
- [Fireworks AI fine-tuning](https://docs.fireworks.ai/fine-tuning/fine-tuning-models)
*Self-hosted LoRA / QLoRA:*
- [Unsloth](https://github.com/unslothai/unsloth)
- [Hugging Face PEFT](https://huggingface.co/docs/peft/index)
*Technique and closed-weight distillation:*
- [Thinking Machines: LoRA Without Regret](https://thinkingmachines.ai/blog/lora/)
- [Thinking Machines: On-Policy Distillation](https://thinkingmachines.ai/blog/on-policy-distillation/)
- [OpenAI distillation guide](https://platform.openai.com/docs/guides/distillation)
### Closing thought
I kept this checklist deliberately abstract. Provider APIs, pricing pages, and reasoning parameters change every few months. The underlying failure modes (unstable prefixes, oversized tool payloads, unbounded loops, narrating instead of rendering) do not. A checklist that names a specific product would be out of date by the next quarter. One that names a pattern stays useful for longer.
That abstraction also makes the checklist easy to use with agentic coding tools. You can paste one or two bullets from here into Claude Code, Cursor, or a similar assistant, point it at your harness code, and let it hunt. Prompts as simple as *"check whether anything in our system prompt would invalidate prompt caching"* or *"find places where we attach the full tool catalog to every request"* are usually enough to surface real issues. Agents are good at pattern-matching the structural problems this checklist describes. They are less good at judging whether a proposed fix actually saved money. That still needs traces and numbers from production.
So treat this as a review rubric, not a recipe. Walk the list, delegate the mechanical parts to an agent, look at traces where the question is quantitative, and leave the deeper engineering work (routing layers, fine-tuning, distillation) until after the boring work is done. Most cost problems in agent systems are not glamorous. They begin with sloppy harness decisions, and the cheapest token is still the one you never send.
---
# Agents Can Reason. They Still Can't Really Search.
> Agents have a search problem across the whole stack: web search, RAG, tool discovery, skills/workflow loading, and even context compaction.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/agents/agent-search-problem/
- Published: 2026-03-16
- Updated: 2026-03-19
- Tags: agents, rag, search, mcp, llm
---
Modern agents can write code, call APIs, draft a memo, and pass a benchmark. That part is real. Put one in front of a clean, well-scoped task and it can look genuinely magical.
Then you ask it to do something normal.
Find the pricing page for a competitor that just relaunched their site. Pull a clause from a regulatory filing hidden inside a government portal. Answer a question that requires connecting facts spread across three internal docs written by people who already left the company. Deploy to an infrastructure setup with custom flags, a weird CI config, and a workaround for a flaky pre-push hook that somebody documented once in a Notion page nobody can find. Or just pick the right tool from a catalog of sixty.
This is where things start falling apart.
Not because the model suddenly forgot how to reason. Not because the prompt is missing some sacred incantation. The failure is more basic than that, and once you see it, you start seeing the same bug everywhere.
Trying to get OpenClaw agents to do useful work is like trying to win at trading crypto - only the top 1% win.
The rest of us end up being the lobster meat for the host in the shell.
OpenClaw agents are terrible at executing complex multi step processes that require delegation.…
## The recurring bottleneck is search
Search here means one simple thing: before an agent can reason well, it has to find the right thing.
That "thing" might be:
- a source on the public web
- a useful chunk from your private docs
- the right tool or MCP action
- the right skill or procedure
- the relevant part of a long context window
Agents fail on real-world tasks because they keep running into this problem in different places. If any one of those breaks, the whole task usually breaks with it.
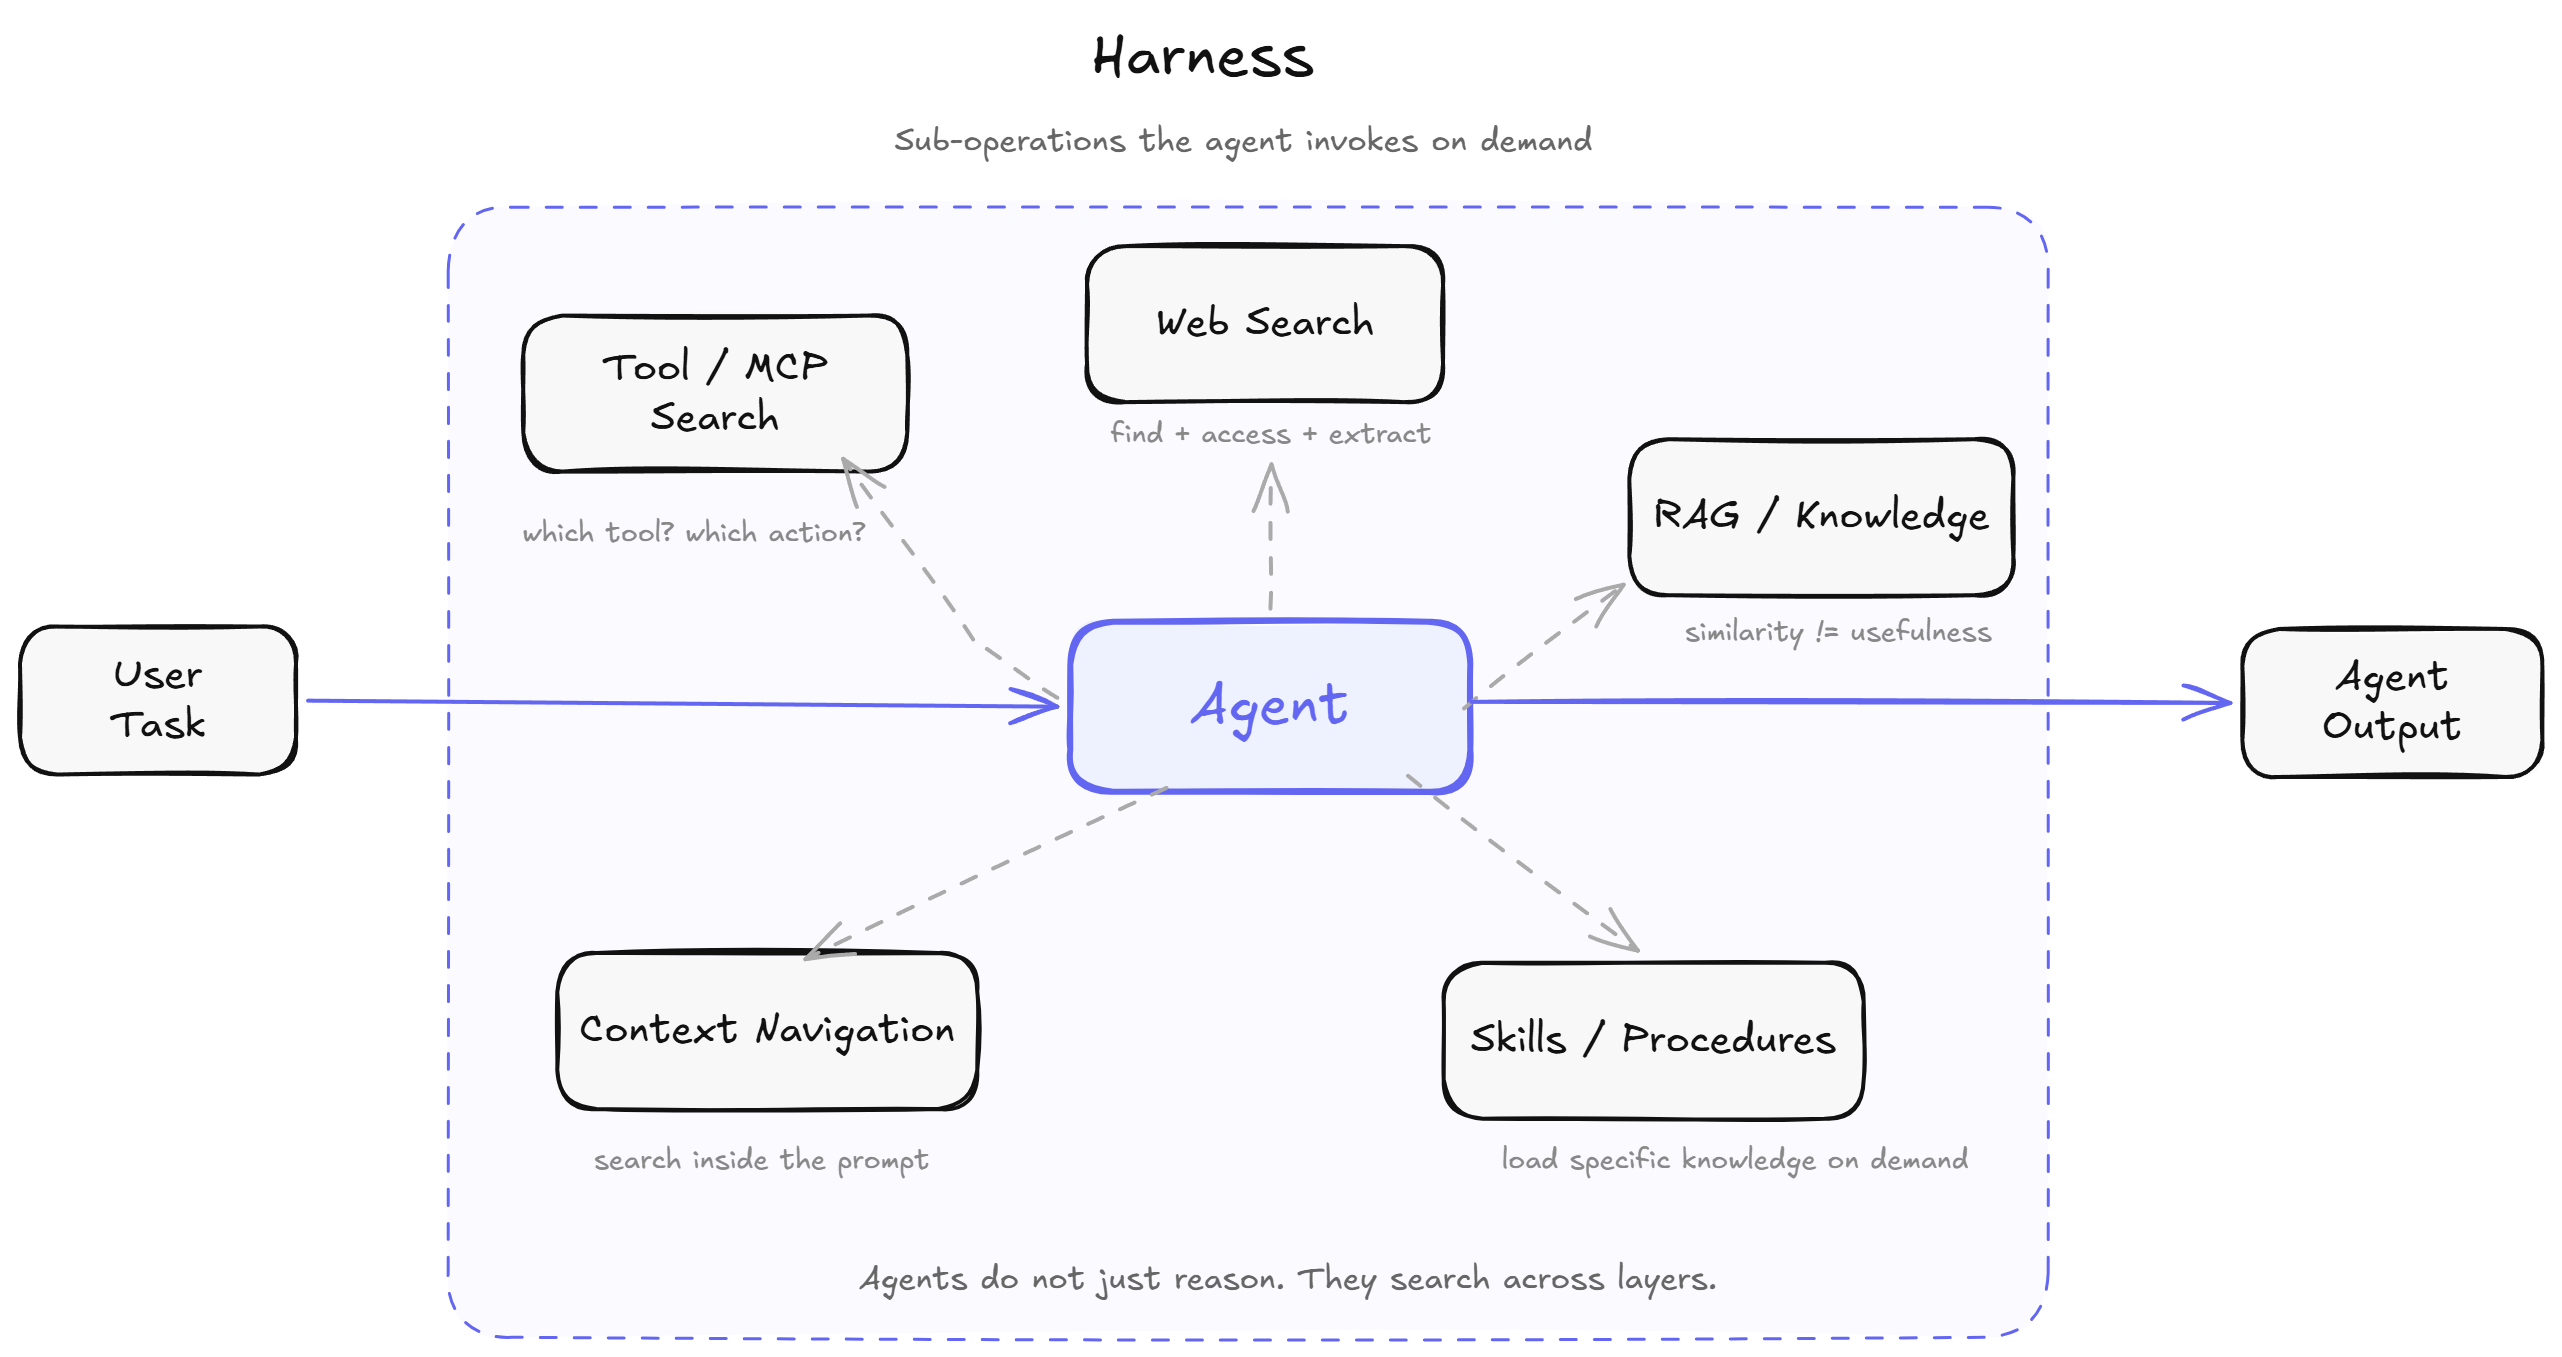
You can see the same pattern in a few different places:
- web and external search
- knowledge retrieval over private documents
- tool and MCP discovery
- skill and procedure loading
- navigation inside long context itself
That last category matters more than it seems. A context window is only useful if the model can find the right thing inside it at the right time. Bigger context windows do not remove search. They just move search inside the model.
The rest of this post walks through each one.
## Problem 1: The web was not built for agents
Let's start with the obvious version of the problem: web search.
Agents need web search for very ordinary reasons:
- a personalized daily digest has to know what happened today, not at pretraining cutoff
- a market-monitoring agent has to track competitor pricing, product launches, and changelogs
- a research agent has to verify claims against primary sources
- a shopping or travel agent has to compare pages that change constantly
- a coding agent has to read the latest docs, issues, and release notes
In other words, the minute the task depends on freshness, verification, or public evidence, the agent needs the web.
Most teams assume this part is already solved. Add a built-in web search tool, get citations back, move on.
But web search for an agent is not a simple lookup. It is a pipeline:
- come up with the right query
- pick the right source
- actually load the page
- render it if JavaScript is involved
- extract the useful part from noisy HTML
- decide whether the evidence is enough
- refine the query and try again if needed
Any one of those steps can fail.
Consider a founder building a competitive intelligence agent. The agent finds the right company page. The page is JavaScript-rendered. Cloudflare is blocking the headless browser. The content that matters is behind a soft login wall. The web search tool returned the URL. Getting what is actually on the page is a different product entirely, which is why [Browserbase](https://docs.browserbase.com/features/stealth-mode) sells stealth mode, CAPTCHA solving, proxies, and even highlights its [Cloudflare signed agents](https://www.browserbase.com/blog/browserbase-cloudflare) work. That product exists because the failure mode is real and systematic.
Agents do not browse the web the way humans do. They negotiate with it.
The managed web search tools from frontier labs such as OpenAI, Anthropic, and Google are useful. They return citations, handle some of the pipeline, and are now billed as explicit line items separate from model tokens. OpenAI and Anthropic both price web search at $10 per 1,000 searches. That pricing signal matters. The industry has already admitted that retrieval is not some free background utility. It is its own product surface with its own cost structure.
But even with those tools, the hard part is not fully solved. Provider-native search is great when you want "an answer with citations." It is much weaker when you need repeated monitoring, raw page access, extraction from messy sites, deeper iteration, or a reliable fetch primitive inside your own agent stack. A competitor-tracking agent, for example, does not just need a summarized answer. It needs the actual pricing page, the changed sections, maybe the FAQ, maybe the release notes, and often the raw content for comparison over time.
That gap is exactly why [Firecrawl](https://firecrawl.dev), [Exa](https://exa.ai), [Tavily](https://tavily.com), and [Parallel](https://parallel.ai/products/search) exist. Firecrawl's own [search API](https://docs.firecrawl.dev/features/search) exposes `scrapeOptions` because "find the page" and "get the useful content" are different operations. Parallel makes the same point from another angle: its [Search API](https://docs.parallel.ai/search/search-quickstart) is pitched as collapsing the traditional search -> scrape -> extract pipeline into one API, and its [Search MCP](https://docs.parallel.ai/integrations/mcp/search-mcp) exposes `web_search` and `web_fetch` as the basic primitives for agents. Their product language is useful because it indirectly admits the same thing: agent search is not just ranking links. It is discovery plus access plus extraction plus compression for the next reasoning step.
## Problem 2: RAG solved the easy slice
Now let's move one layer inward.
The first generation of retrieval-augmented generation made the problem look tractable. Embed your documents, store vectors, retrieve the top-k most similar chunks, append them to the prompt. For narrow, well-scoped, single-hop questions over a clean corpus, this works.
It breaks on anything harder.
Suppose you build a technical QA system over internal docs. Single-hop questions work well. Then someone asks a question that requires connecting a constraint described in one document with a definition from another and a caveat buried in a third. Cosine similarity returns three chunks that look individually relevant, but they do not compose into an answer. The model finds each piece, but the retrieval step never actually bridges the gap between them.
This failure is not accidental. It is structural. Similarity is not the same as usefulness. A chunk can be semantically close to a query and still be useless for the final answer. Another chunk can look semantically distant and still be essential for a reasoning step three hops later. This is exactly why IRCoT (interleaving retrieval with chain-of-thought, ACL 2023) and Self-RAG exist as research directions. One-shot retrieve-then-read hit a real ceiling, so the field moved toward iterative and adaptive retrieval.
So the evolution is straightforward:
- simple RAG: retrieve once, read once
- better RAG: retrieve, reflect, and try again
- agentic RAG: break the problem apart, search in parallel, merge evidence, decide whether more search is needed
This is why "agentic RAG" is now becoming a product surface, not just a paper idea. Azure AI Search now has [agentic retrieval](https://learn.microsoft.com/en-us/azure/search/search-agentic-retrieval-concept), where an LLM breaks a complex query into smaller subqueries, runs them in parallel, and merges the result. Their own example is basically a multi-hop retrieval problem in plain English: "find me a hotel near the beach, with airport transportation, and that's within walking distance of vegetarian restaurants." That kind of query is awkward for classic one-shot retrieval, but much better suited to query decomposition plus parallel search.
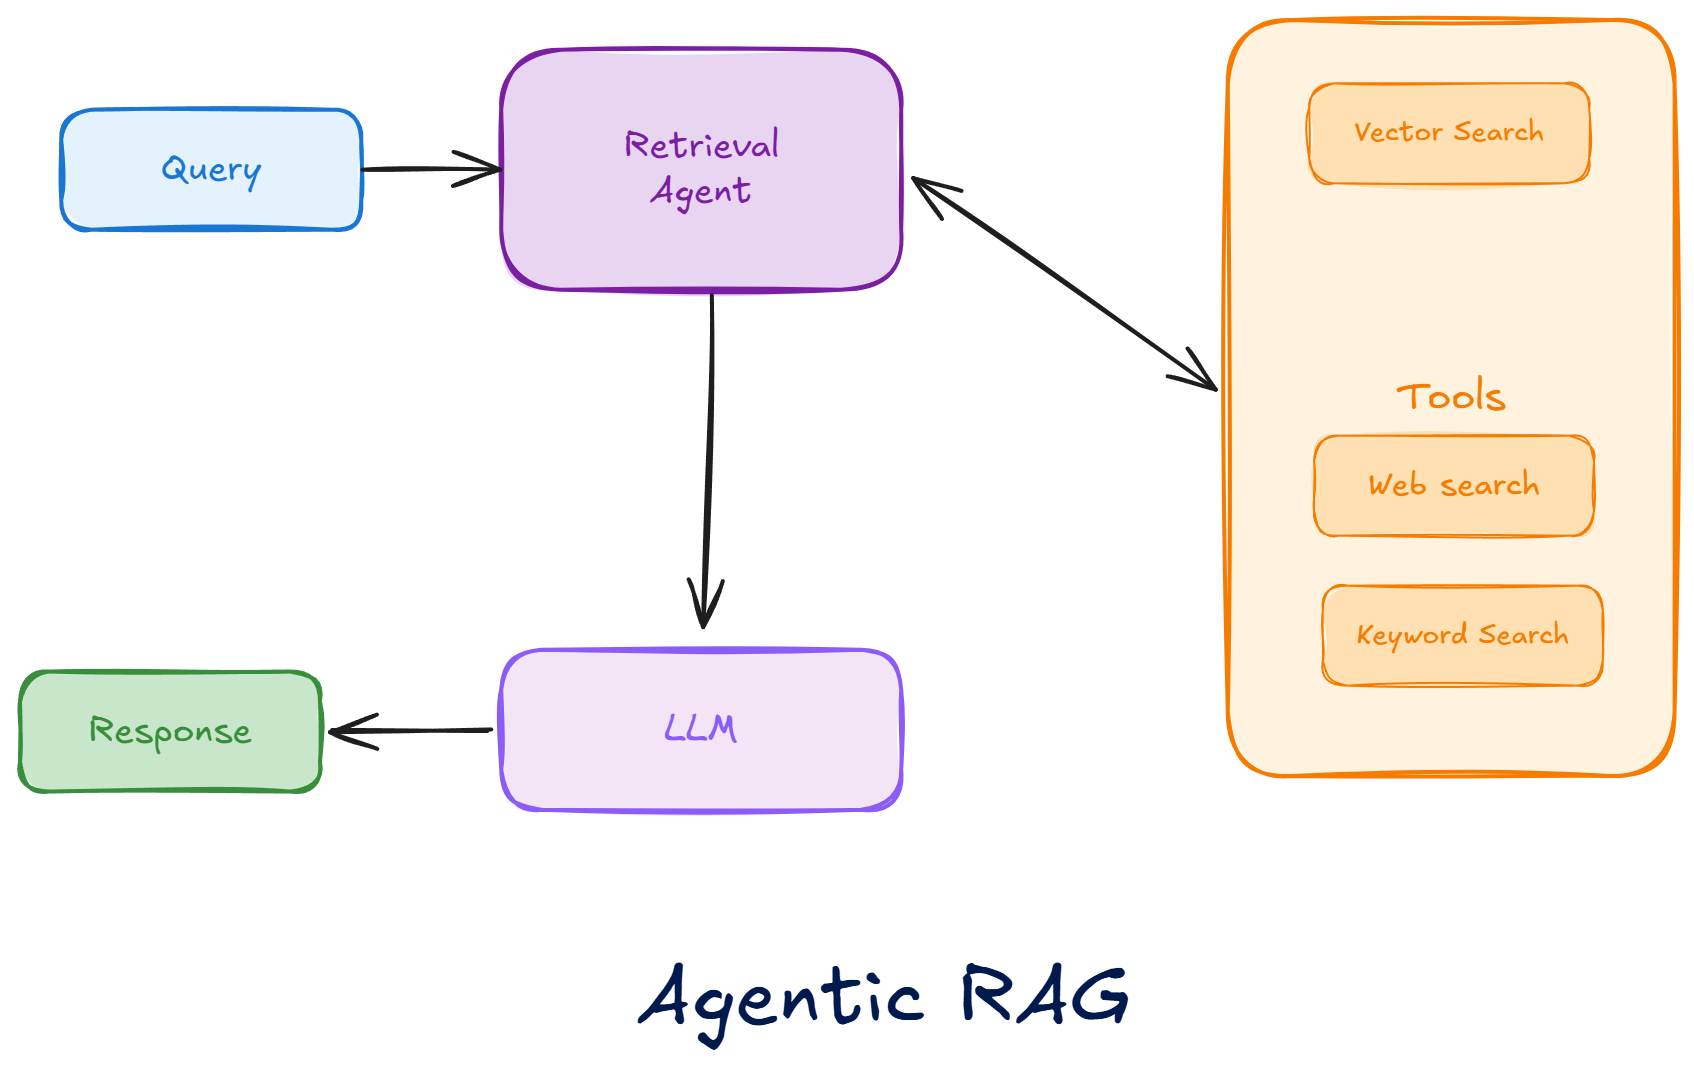
So yes, agentic RAG is solving a real problem. It is helping with multi-hop questions, multi-ask queries, and situations where the original user query is too broad or under-specified for one retrieval pass.
But it is still far from fully solved.
Even after you decompose a question well, a bunch of hard problems remain:
- the needed source might not be indexed at all
- the relevant page might be stale, contradictory, or poorly chunked
- the evidence might live across text, tables, and UI state instead of neat paragraphs
- one subquery can retrieve locally relevant passages that are still useless for the final answer
- the system still has to decide when it has enough evidence and when to keep searching
- each extra retrieval step adds latency and cost
Microsoft's own [agentic retrieval docs](https://learn.microsoft.com/en-us/azure/search/search-agentic-retrieval-concept) say the LLM-based query planning adds latency, even if parallel execution helps compensate. That tradeoff is important. Agentic RAG is not a free accuracy upgrade. It is a better search policy with more moving parts.
A very normal real-world example is enterprise support. A user asks: "Does our enterprise plan support SSO for contractors, what changed in the last release, and are there regional limits for EU tenants?" The answer might live across pricing docs, old help-center pages, release notes, and an internal policy page. Agentic RAG is clearly better than one-shot top-k retrieval here because it can break the question apart. But it can still fail if one of those sources is stale, if the important caveat is hidden in a table, or if the retrieval system stops after finding something merely plausible.
And this gets worse as the organization gets bigger.
At small scale, RAG usually fails in understandable ways: bad chunking, weak embeddings, poor prompts. At big-company scale, it starts failing for more boring reasons:
- the same fact exists in five places, but only one copy is current
- permissions mean the best document exists, but the system cannot show it to this user
- different teams store knowledge in different tools with different metadata quality
- highly selective filters improve security but can hurt recall or latency
- constant document churn means the index is always racing reality
- vector storage and query cost stop being abstract and start becoming infrastructure constraints
This is why enterprise search products like [Glean](https://www.glean.com/searchengine) keep emphasizing 100+ connectors and real-time permissions-aware retrieval. They are not doing that for marketing decoration. They are reacting to the actual shape of the problem inside big companies: knowledge is fragmented across Slack, Confluence, Jira, Google Drive, Notion, wikis, tickets, PDFs, and internal apps, and the permission model is part of retrieval, not an afterthought.
Even the lower-level search infrastructure shows the same pain. Azure AI Search's [vector filter documentation](https://learn.microsoft.com/en-us/azure/search/vector-search-filters) explicitly calls out a tradeoff between filtering, recall, and latency, and notes that some filter modes can produce false negatives for selective filters or small `k`. That matters a lot in enterprises because security and access control are often implemented as filters. So the retrieval system is not just trying to find the most relevant passage. It is trying to find the most relevant passage among the subset this user is allowed to see, while still being fast enough to feel interactive.
There is also a scale tax on the index itself. Azure documents [vector index size limits](https://learn.microsoft.com/en-us/azure/search/vector-search-index-size) and [storage tradeoffs](https://learn.microsoft.com/en-us/azure/search/vector-search-how-to-storage-options) because large corpora consume memory and can require multiple stored copies depending on the workload. So even before the model starts reasoning, the retrieval layer is already trading off freshness, cost, recall, latency, and access control. A very normal enterprise question like "What is the current travel reimbursement policy for contractors in Germany?" can span an HR PDF, a newer policy page, a regional addendum, a legal exception in shared drive, and a stale Slack workaround. The hard part is not generating the answer. The hard part is finding the newest authoritative source and ignoring the plausible but outdated ones.
RAG treated retrieval like a database lookup. Agentic systems reveal that retrieval is closer to exploration.
## Problem 3: MCP and tools moved the problem up the stack
The Model Context Protocol gave agents a standard way to connect to tools. This is genuinely useful. It also made something more obvious: tools themselves are now a search problem.
Once an agent has access to fifty or more tools, it runs into a familiar problem in a new form. Which tool is relevant? Which action name is correct? Is authentication already set up? Which capabilities should even be visible right now?
Anthropic's own [advanced tool use documentation](https://docs.anthropic.com/en/docs/agents-and-tools/tool-use/implement-tool-use) puts a number on this: large tool catalogs can push tool definitions past 50,000 tokens before the model has even read the user's request. Their recommended fix is to use a smaller retrieval model to return only the relevant tools based on user intent, and even use semantic search over tool descriptions. That recommendation is RAG. For actions.
And the ecosystem is already moving in that direction. Anthropic's own [advanced tool use engineering post](https://www.anthropic.com/engineering/advanced-tool-use) says agents should "discover and load tools on-demand" instead of stuffing every definition into context upfront. [LangGraph added dynamic tool calling](https://changelog.langchain.com/announcements/dynamic-tool-calling-in-langgraph-agents) so the available tools can change at different points in a run. Their examples are telling: require an auth tool before exposing sensitive actions, start with a small toolset, then expand as the task evolves. [Salesforce's DX MCP blog](https://developer.salesforce.com/blogs/2025/06/level-up-your-developer-tools-with-salesforce-dx-mcp) makes the same move with toolsets, noting that hosts can dynamically load only the tools they need to minimize memory use and improve performance.
That is the deeper point. The problem is not just "which tool should the model call?" The problem is also "which tools should even be attached right now?" Static attachment made sense when agents had a handful of tools. It breaks down when the catalog is large, sensitive, or step-dependent. So now we are seeing dynamic tool attachment, scoped tool exposure, and tool retrieval as separate design patterns.
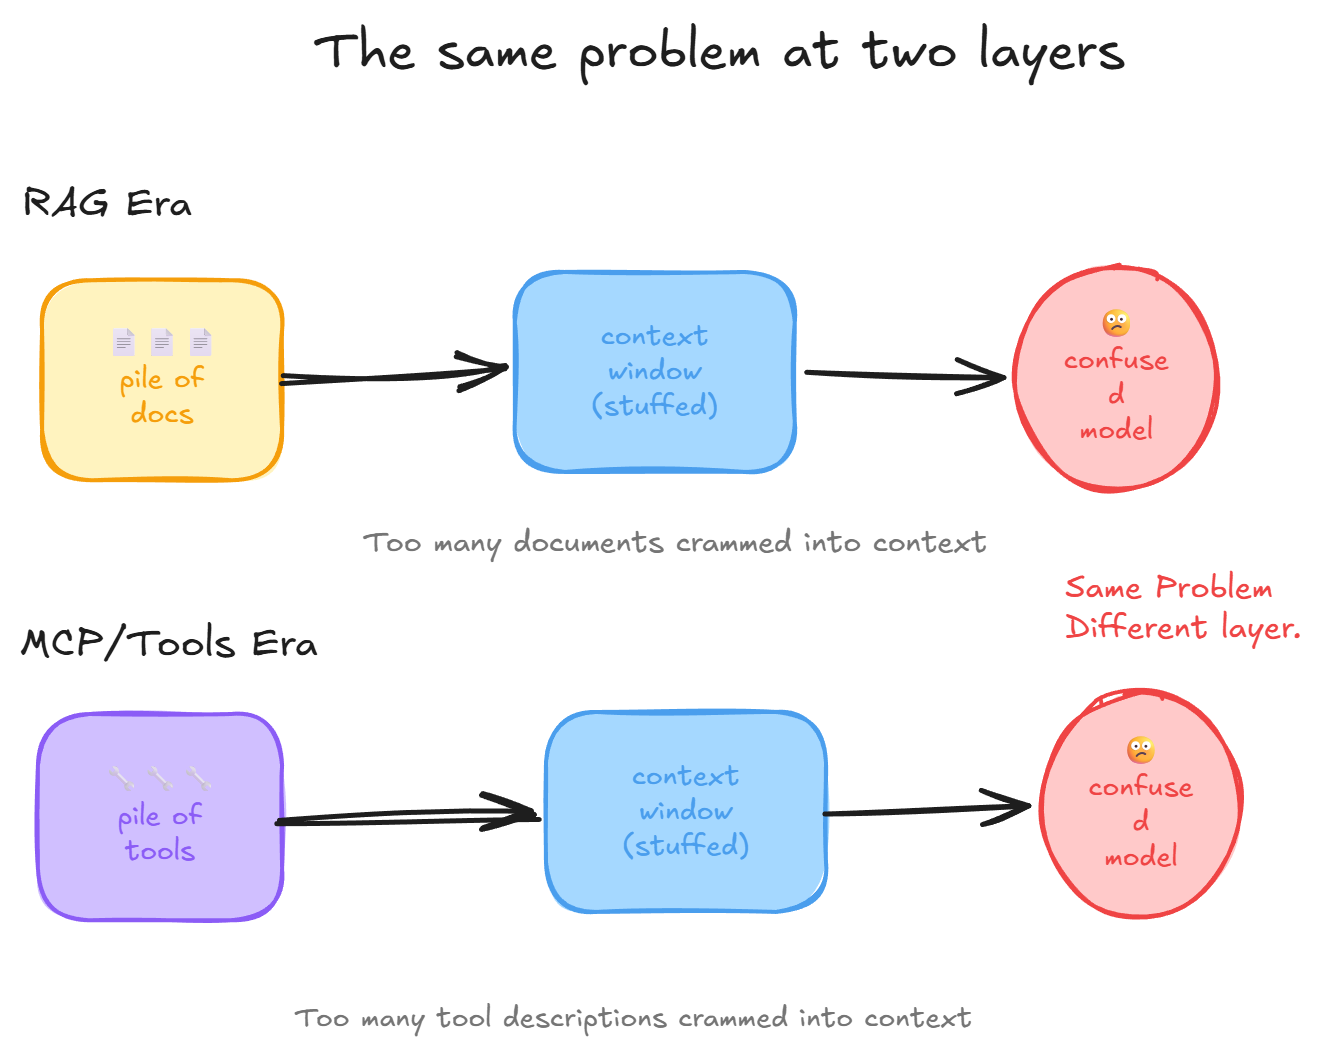
We solved document overload by inventing retrieval. Now we are rebuilding the same fix for tools. [Composio's Tool Router](https://docs.composio.dev/reference/api-reference/tool-router), which explicitly searches, plans, and authenticates across tool ecosystems, is basically a retrieval layer for actions. Even outside product docs, the ecosystem keeps describing the same pain: Apify recently summarized the MCP moment as context overload, auth pain, and failed tool calls everywhere. Once you have enough MCP servers, you need search to find your search tools.
## Problem 4: Skills are workflow search
At this point, there is one more kind of thing the agent needs to find: workflow.
Agents do not just lack facts and tools. They also lack reusable, environment-specific know-how.
Using Skills well is a skill issue.
I didn't quite realize how much until I wrote this, the best can completely transform how your team works. https://t.co/a0kbhdHdyf
Consider a coding agent that needs to deploy to an internal infrastructure with custom build flags, a non-standard CI configuration, and a known workaround for a flaky pre-push hook. None of this is in pretraining. Without a skill, the agent has to rediscover the workaround by trial and error every time. It burns tokens, fails steps, and eventually needs help. With a skill, it loads the procedure on demand, executes it, and moves on.
Skills are what happens when you stop making the agent rediscover the same workflow every turn.
This is also where the ecosystem is starting to converge on a few file-level conventions.
At the project layer, we now have dedicated memory files such as `AGENTS.md` and `CLAUDE.md`. They look similar, but they are solving a slightly different problem than skills.
- `AGENTS.md` is emerging as a simple open format for repo-level instructions for coding agents
- OpenAI explicitly recommends `AGENTS.md` for Codex so the agent can learn repo conventions, testing commands, and project-specific gotchas
- Anthropic uses `CLAUDE.md` as Claude Code's project memory, with a hierarchy that can include enterprise, project, and user-level memory files
These files are useful, but they are not the whole answer. They are mostly always-on project memory. Skills are more selective. They are a way to package a reusable capability so the agent can discover it and load it only when needed.
The core issue is simple: you cannot stuff every workflow into the prompt. OpenAI's own Codex engineering write-up says the "one big `AGENTS.md`" approach failed and that `AGENTS.md` works better as a map than as an encyclopedia. That is the same pattern we keep seeing everywhere else. Once the context gets large enough, the problem becomes navigation again.
So the stack is starting to separate into two layers:
- `AGENTS.md` / `CLAUDE.md` for always-on project memory
- `SKILL.md` / `skill.md` for workflows that should be loaded on demand
That second layer is getting standardized too. [OpenClaw treats skills as Agent Skills-compatible folders](https://docs.openclaw.ai/skills), the [Agent Skills specification](https://agentskills.io/specification) defines `SKILL.md` with progressive disclosure, [Vercel's skills ecosystem](https://vercel.com/changelog/introducing-skills-the-open-agent-skills-ecosystem) is pushing the same format across agents, and [Mintlify now auto-generates `skill.md`](https://www.mintlify.com/docs/ai/skillmd) for docs. The reason this works is straightforward: [Hermes uses progressive disclosure for skills](https://hermes-agent.nousresearch.com/docs/user-guide/features/skills/) because not every workflow should live in prompt context all the time. Some workflows need their own retrieval layer.
Documents answer *what is true*. Tools answer *what can I do*. Skills answer *how should I do it here*.
## Problem 5: A bigger context window is a larger search space
Now for the part I think people still under-appreciate: context itself.
The common response to long-context failures is simple. If the model cannot find the relevant information, give it a bigger context window. This framing is almost exactly backwards.
A larger context window does not automatically improve the model's ability to locate what matters inside it. It increases the size of the space the model has to navigate. The bottleneck is not room. It is navigation.
Consider a research agent processing a 200-page technical report. The binding constraint appears on page four. The answer that depends on it is on page 180. The model can individually look at both sections and still fail to connect them. This is basically the "lost in the middle" problem: relevant information buried inside a long input is used less reliably than information near the edges.
And once you look at real agent products, you can see that everyone has quietly accepted this. Nobody is relying on "just make the window bigger" as the only answer anymore. They are all building context-management systems on top.
The choices differ by provider, but the pattern is the same.
- OpenAI is leaning into native compaction. In the Codex stack, the conversation gets compacted automatically once it crosses a threshold. Their newer `/responses/compact` flow does not just replace old messages with a plain-English summary; it returns a smaller list of items plus a special compaction item intended to preserve more of the model's latent understanding across context-window boundaries. That is a very specific design choice: compress the past, keep the task moving, and treat context management as part of the runtime.
- Anthropic exposes compaction much more directly at the product layer. Claude Code has auto-compact, a manual `/compact` command, optional focus instructions like `/compact Focus on code samples and API usage`, and even `CLAUDE.md` hooks for custom summary instructions. That is a different design choice: context compaction is explicit, steerable, and summary-driven.
- Google has pushed harder on a different axis: very large context windows and context caching. Gemini 3 emphasizes 1M-token context, and the Gemini API has both implicit and explicit context caching so repeated prefixes can be reused across requests. Gemini CLI also emphasizes checkpointing to save and resume longer sessions. That is not exactly the same as compaction, but it is still a context-management strategy. Instead of aggressively shrinking the conversation, it tries to give you more room, reuse the expensive prefix, and resume work when needed.
So the choices are different:
- bigger windows
- summarization and compaction
- checkpointing and resume
- persistent project memory files
- cached prefixes across requests
But all of them are really answers to the same question: how does the agent keep the right parts of history available without drowning in the whole history?
This is why [Recursive Language Models](https://github.com/aiwavecomputer/recursive-lm) introduce explicit navigation operators such as peek, partition, grep, and zoom instead of just extending sequence length forever. Those are search operations over context. Related work like [LCM](https://papers.voltropy.com/LCM) makes the same point from another angle: long context and local search need to work together. Once you look at it this way, recursive context methods start looking less like magic context scaling and more like retrieval policies over an internal search space.
Context engineering is just search engineering with better marketing.
## Conclusion: Search keeps coming back
Search keeps showing up everywhere: on the public web, inside RAG systems, across tool and MCP catalogs, inside skills and workflow loading, and even inside the context window itself.
That is why so many people are attacking the problem from different angles. Some are building better web-search stacks. Some are building agentic RAG. Some are building tool routers and dynamic attachment. Some are building skills, memory files, compaction, caching, and context-navigation systems. They all look different, but they are all trying to solve the same thing.
If agents can reliably solve search across all of these surfaces, that would be a huge capability jump. It would mean they can consistently find the right evidence, the right tool, the right workflow, and the right context before acting. That gets us much closer to agents that feel robust, general, and meaningfully closer to AGI in practice.
*Can anyone turn web search, knowledge retrieval, tool discovery, workflow/skills loading, and context navigation into one coherent search runtime for agents, or is this the hard part that keeps standing between today's agents and something much closer to AGI?*
---
*References:*
- Apify X post on MCP pain: [x.com/apify/status/2011556498477105383](https://x.com/apify/status/2011556498477105383)
- Agent Skills: [Specification](https://agentskills.io/specification)
- AGENTS.md: [Open format](https://agents.md/)
- Anthropic advanced tool use guide: [Tool use implementation](https://docs.anthropic.com/en/docs/agents-and-tools/tool-use/implement-tool-use)
- Anthropic engineering: [Advanced tool use](https://www.anthropic.com/engineering/advanced-tool-use)
- Anthropic Claude Code memory: [CLAUDE.md memory](https://docs.anthropic.com/en/docs/claude-code/memory)
- Anthropic Claude Code costs: [Compaction and auto-compact](https://docs.anthropic.com/en/docs/claude-code/costs)
- Anthropic Claude Code slash commands: [Slash commands](https://docs.anthropic.com/en/docs/claude-code/slash-commands)
- Azure AI Search: [Agentic retrieval](https://learn.microsoft.com/en-us/azure/search/search-agentic-retrieval-concept)
- Azure AI Search: [Vector filters](https://learn.microsoft.com/en-us/azure/search/vector-search-filters)
- Azure AI Search: [Vector index size](https://learn.microsoft.com/en-us/azure/search/vector-search-index-size)
- Azure AI Search: [Vector storage options](https://learn.microsoft.com/en-us/azure/search/vector-search-how-to-storage-options)
- Browserbase Cloudflare post: [Browserbase + Cloudflare](https://www.browserbase.com/blog/browserbase-cloudflare)
- Composio Tool Router: [Tool Router API](https://docs.composio.dev/reference/api-reference/tool-router)
- Firecrawl search docs: [Search API](https://docs.firecrawl.dev/features/search)
- Glean: [Enterprise search engine](https://www.glean.com/searchengine)
- Gemini 3: [1M context window](https://ai.google.dev/gemini-api/docs/gemini-3)
- Gemini API: [Context caching](https://ai.google.dev/gemini-api/docs/caching/)
- Gemini CLI: [Checkpointing and GEMINI.md](https://github.com/google-gemini/gemini-cli)
- Hermes skills: [Progressive disclosure](https://hermes-agent.nousresearch.com/docs/user-guide/features/skills/)
- IRCoT, Trivedi et al. (ACL 2023): [Interleaving Retrieval with Chain-of-Thought Reasoning](https://aclanthology.org/2023.acl-long.557/)
- LCM: [Long Context Models and local search](https://papers.voltropy.com/LCM)
- LangGraph: [Dynamic tool calling](https://changelog.langchain.com/announcements/dynamic-tool-calling-in-langgraph-agents)
- Mintlify: [skill.md](https://www.mintlify.com/docs/ai/skillmd)
- OpenAI: [How OpenAI uses Codex to build Codex](https://openai.com/index/how-openai-uses-codex-to-build-codex/)
- OpenAI: [Harness engineering for an agent-centric world](https://openai.com/index/harness-engineering-for-an-agent-centric-world/)
- OpenAI: [Unrolling the Codex agent loop](https://openai.com/index/unrolling-the-codex-agent-loop/)
- Self-RAG, Asai et al. (NeurIPS 2023): [Self-RAG: Learning to Retrieve, Generate, and Critique](https://openreview.net/forum?id=hSyW5go0v8)
- Salesforce DX MCP: [Dynamic toolsets](https://developer.salesforce.com/blogs/2025/06/level-up-your-developer-tools-with-salesforce-dx-mcp)
- Lost in the Middle, Liu et al. (TACL 2024): [How Language Models Use Long Contexts](https://direct.mit.edu/tacl/article/doi/10.1162/tacl_a_00638/119630/)
- OpenClaw skills: [Skills docs](https://docs.openclaw.ai/skills)
- Parallel Search API: [Search quickstart](https://docs.parallel.ai/search/search-quickstart)
- Parallel Search MCP: [Search MCP](https://docs.parallel.ai/integrations/mcp/search-mcp)
- Parallel Search product: [Parallel Search](https://parallel.ai/products/search)
- Recursive Language Models: [Paper](https://arxiv.org/pdf/2510.06252) · [Repo](https://github.com/aiwavecomputer/recursive-lm)
- Vercel: [Introducing skills](https://vercel.com/changelog/introducing-skills-the-open-agent-skills-ecosystem)
- Browserbase stealth mode: [docs.browserbase.com/features/stealth-mode](https://docs.browserbase.com/features/stealth-mode)
---
# Bits per byte (BPB) for LLMs: tokenizer-agnostic loss
> BPB measures LLM loss per UTF-8 byte, making tokenizer comparisons fair. Formula, worked example, and PyTorch-style implementation.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/llm/bits-per-byte/
- Published: 2025-10-15
- Updated: 2026-06-17
- Tags: llm, tokenizer
---
> Karpathy recently released [nanochat repo](https://github.com/karpathy/nanochat/) which cotains code for **training the best ChatGPT under $100**. While skimming the high level code, I noticed across `bits per bytes` instead of typical `cross entropy` loss. And, i found it interesting, so i decided to dig in.
### TL;DR
- Bit per byte (BPB) is just cross-entropy measured per byte. We divide cross-entropy by bytes and log(2) to convert to bits.
- Because it’s per byte, BPB is tokenizer-agnostic and lets you compare models fairly even when they use different vocabularies and rules.
- Perplexity and token-level loss change when you change the tokenizer; BPB largely doesn’t.
LLM doesn't predict the text, it predicts the (next) token. But token definitions depend on the tokenizer (BPE, Unigram, merges, special tokens, etc.). Swap tokenizers and the same sentence can become more or fewer tokens. So `per-token` metrics (avg CE, perplexity) change even if the underlying modeling quality didn’t.
Some popular tokenizer choices are:
| Model | Tokenizer | Vocab Size |
|-------|-----------|------------|
| GPT-4 | cl100k_base (BPE) | 100,256 |
| LLaMA 3 | TikToken (BPE) | 128,000 |
| Gemini 2.5 | SentencePiece (Unigram) | 256,000 |
| Claude | closed-source | undisclosed |
Different tokenizers ≠ comparable "tokens". So a model that uses a coarser tokenizer (fewer, longer tokens) can appear to have a lower per-token loss or perplexity, simply because the denominator changed.
Instead of normalizing loss per token, normalize per byte of UTF-8 text that those tokens represent. Then, no matter how you split words into tokens, you're still asking: how many bits, on average, does the model need to encode each byte of text?
### Example: Why Per-Token Metrics Mislead
Consider two models predicting "The Capital of India" -> " is Delhi" (8 bytes in UTF-8, including the space):
**Model A** (coarse tokenizer):
- Tokens: `[" is", " Delhi"]` (2 tokens)
- Per-token loss: `[1.5, 4.5]` nats
- Total loss: 6.0 nats
**Model B** (fine-grained tokenizer):
- Tokens: `[" is", " Del", "hi"]` (3 tokens)
- Per-token loss: `[1.5, 2.0, 2.5]` nats
- Total loss: 6.0 nats
**Per-token metrics (misleading):**
```bash
Model A avg loss: 6.0 / 2 = 3.0 nats/token
Model B avg loss: 6.0 / 3 = 2.0 nats/token ← appears better!
Model A perplexity: exp(3.0) = 20.09
Model B perplexity: exp(2.0) = 7.39 ← appears better!
```
Model B looks significantly better, but it's the **same 6.0 nats** spread over more tokens.
**Bits-per-byte (fair comparison):**
```bash
Model A BPB: 6.0 / (ln(2) × 8) = 1.08 bits/byte
Model B BPB: 6.0 / (ln(2) × 8) = 1.08 bits/byte ← identical!
```
BPB correctly shows both models have the same predictive quality. The apparent "improvement" in Model B's per-token metrics was purely an artifact of tokenization granularity.
### Implementation
Below is the simplified and more readable version of the [original code](https://github.com/karpathy/nanochat/blob/master/nanochat/loss_eval.py).
```python
import math
import torch
import torch.distributed as dist
@torch.no_grad()
def evaluate_bpb(model, batches, steps: int, token_bytes: torch.Tensor) -> float:
"""
Compute Bits-Per-Byte (BPB) over `steps` batches.
Shapes (your mental model):
B = batch size
Seq = sequence length
V = vocab size
Inputs:
- model: callable like model(x, y, loss_reduction='none') -> loss per token.
Expects:
x: (B, Seq) token ids (int64)
y: (B, Seq) target token ids (int64), may contain ignore_index (<0)
Returns:
loss2d: (B, Seq) per-token loss in NATs (float32/float16)
- batches: iterable yielding (x, y) as above.
- steps: number of batches to evaluate.
- token_bytes: (V,) int64 — byte length of each token id; 0 for special tokens
(those should not count toward BPB).
Notes:
- BPB = (sum of losses in NATs over *counted* tokens) / (ln(2) * total_counted_bytes)
- Tokens contribute to the denominator by their byte length; tokens with 0 bytes
(specials) and ignored targets (<0) are excluded from both numerator & denominator.
"""
device = model.get_device() if hasattr(model, "get_device") else next(model.parameters()).device
# Accumulators across steps (and later across ranks)
sum_nats = torch.tensor(0.0, dtype=torch.float32, device=device) # scalar
sum_bytes = torch.tensor(0, dtype=torch.int64, device=device) # scalar
token_bytes = token_bytes.to(device=device, dtype=torch.int64) # (V,)
batch_iter = iter(batches)
for _ in range(steps):
x, y = next(batch_iter) # x: (B, Seq), y: (B, Seq)
x = x.to(device)
y = y.to(device)
loss2d = model(x, y, loss_reduction='none') # (B, Seq) NATs
loss1d = loss2d.reshape(-1) # (B*Seq,)
y1d = y.reshape(-1) # (B*Seq,)
if (y1d < 0).any():
# Mask out ignore_index (<0) before indexing into token_bytes
valid = (y1d >= 0) # (B*Seq,)
ysafe = torch.where(valid, y1d, torch.zeros_like(y1d)) # (B*Seq,)
nb = torch.where(valid, token_bytes[ysafe], torch.zeros_like(y1d)) # (B*Seq,) int64
else:
nb = token_bytes[y1d] # (B*Seq,) int64
# Count only tokens with positive byte length
counted = (nb > 0) # (B*Seq,) bool
sum_nats += (loss1d[counted]).sum() # scalar
sum_bytes += nb[counted].sum() # scalar int64
# Distributed sum over all ranks, if initialized
if dist.is_initialized() and dist.get_world_size() > 1:
dist.all_reduce(sum_nats, op=dist.ReduceOp.SUM)
dist.all_reduce(sum_bytes, op=dist.ReduceOp.SUM)
total_nats = float(sum_nats.item())
total_bytes = int(sum_bytes.item())
# Guard against division by zero (e.g., all tokens were special/ignored)
if total_bytes == 0:
return float("nan")
bpb = total_nats / (math.log(2.0) * total_bytes)
return bpb
```
---
# Creativity Is a Luxury
> Creativity is a luxury. It requires time, energy and space.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/life/creativity-is-a-luxury/
- Published: 2025-08-17
- Updated: 2025-12-22
---
Creativity is a luxury.
It demands time, energy and space: things that feel scarce when rent, groceries, and the next shift loom larger than any poem or prototype. Most of us are caught in a slow-spinning loop of laundry, commutes, and alarms that reset before the dream has even ended.
It is also a luxury that needs literal room: a quiet corner, a desk that isn’t the dinner table, a door that closes. I have watched friends whose bedrooms double as storage closets carry old laptops to 24-hour cafés or office lobbies after hours, hunting for any pocket of stillness where code can compile without a toddler tugging at the charger.
Much of the talk about “why they don’t innovate” is aimed at developing nations, as if ingenuity were a switch we forgot to flip. The question forgets that for many, the next level of the game called life is simply surviving this week.
Creativity requires time, the one thing handed out in identical seconds but lived in wildly unequal ways. A developer on bug-fix cycles measures the day in thirty-minute bites between Jira pings; a CTO can clear a whole afternoon to whiteboard a new microservice. Same 24 hours, but one calendar is packed with other people's priorities, the other guarded so ideas can breathe.
Yet even in the squeeze, support engineers still refactor a memory leak during the last hour of their shift, and interns build open-source yet another caching library on hostel Wi-Fi at 2 a.m. Moral richness doesn't wait for perfect conditions; it grows in cracks, stubborn and green, proving that the luxury of creativity is one humans keep insisting on, even when the price feels impossibly high.
Disclaimer
This writing was assisted by an LLM.
---
# GPT-5 router: why chat apps will route across models
> Why GPT-5 style routers send simple prompts to smaller models and hard prompts to reasoning models, and what that means for chat UX.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/llm/gpt5-router/
- Published: 2025-08-13
- Updated: 2026-06-17
- Tags: llm, ux
---
OpenAI GPT-5 Router is like Apple removing headphone jack. It sucks but everyone will follow it.
## What is GPT-5 Router
The GPT-5 router picks the right model for each request in real time. In plain English: easy stuff goes to the small model; complex stuff goes to the big brain. The goal is simple, better answers per dollar and millisecond by mixing models instead of forcing a single static choice. I suspect router will be a key component in subscription pricing.
## How It Works: Routing as Classification Problem
Understanding the router means treating it like a classifier. For example, you have two models: a smaller, no-reasoning model and a larger, reasoning model. Given a user query, the router has to make a call:
- Smaller model: when the query is simple
- Larger model: when the query is complex
In reality, we have more models, but for simplicity, we will stick to two models.
### The Classification Matrix
A compact way to reason about this: a confusion matrix. To keep score, call the positive class "complex" and the negative class "simple". Rows are the router's decision; columns are the true difficulty of user query.
| | Actual Difficulty: Simple | Actual Difficulty: Complex |
|-----------------|----------------------------|----------------------------|
| Route: Smaller | True Negative (TN) | False Negative (FN) |
| Route: Larger | False Positive (FP) | True Positive (TP) |
We don't have to worry about the diagonal elements, as they are the cases where the router is correct. But we need to worry about the off-diagonal elements : False Positive and False Negative.
### Error Analysis: Both Mistakes Cost Money
**False Negative (Complex → Smaller)**: The worst outcome
- Breaks user experience - they get a shallow answer to a deep question
- Damages trust and perceived quality
- Users complain, cancel subscriptions, bad reviews
- Cost: Customer churn and reputation damage
**False Positive (Simple → Larger)**: The expensive mistake
- User gets a great answer but you burn unnecessary compute
- $0.05 query becomes a $0.60 query (12x cost)
- At scale, this adds up fast - 10,000 false positives = $5,500 in wasted compute
- Cost: Direct margin erosion
So the strategy becomes: bias toward false positives (overspend on compute) rather than false negatives (lose customers). You can optimize compute costs later, but you can't win back a user who thinks your AI is "dumber than your previous model."
This is why OpenAI initially erred on the side of caution with the router, then faced backlash when the pendulum swung too far toward false negatives. The sweet spot is narrow and expensive to find.
## Economic Motivation: The Subscription Squeeze
This technical complexity of router exists because OpenAI faces a challenging economic reality: **flat subscription pricing becomes difficult when usage explodes exponentially**. As per Sam Altman, even $200/month struggles to maintain profitability.
insane thing: we are currently losing money on openai pro subscriptions!
### Math Behind the Subscription Pricing
Here's the math behind the subscription pricing:
- Users pay $20/month for supposedly "unlimited" access (Nothing is unlimited)
- But Big models can burn upto $0.5+ per query in compute costs (Reasoning models)
- Deep research runs cost ~$1+ each and take 20+ minutes
- Other features such as memory, tools, etc. are not free.
It's not just OpenAI - other companies are facing similar challenges:
* Anthropic - Their $20/month subscription includes significant rate limiting.
* Cursor - They recently announced that after 250 Sonnet requests, they'll meter usage and charge based on consumption
### Routers are going to get better
Creating a good router is fundamentally a data problem, and OpenAI has a massive advantage here. Every query-response pair becomes training data for router improvement:
**Data Collection at Scale:**
- Millions of daily interactions across different complexity levels
- User feedback signals (thumbs up/down, follow-up questions)
- Engagement metrics (time spent reading, follow-up queries)
- Cost-per-query data for model optimization
**Iterative Improvement Loop:**
- Router misroutes a complex query → user complains or asks follow-up
- OpenAI labels this as "should have gone to reasoning model"
- Router learns: similar queries get routed to larger model next time
- Over time, accuracy improves from 80% → 90% → 95%+
## The GPT-5 Launch Backlash
When OpenAI launched GPT-5 with mandatory routing, users immediately complained about quality degradation. The router was routing too many complex queries to the smaller model, making GPT-5 seem "dumber" than GPT-4o.
**User Backlash:**
- Users reported [shallow answers to complex prompts](https://www.techradar.com/ai-platforms-assistants/chatgpt/chatgpt-users-are-not-happy-with-gpt-5-launch-as-thousands-take-to-reddit-claiming-the-new-upgrade-is-horrible)
- Reddit filled with complaints about the [perceived downgrade](https://www.macrumors.com/2025/08/08/openai-gpt-5-complaints/)
- Loss of manual model selection frustrated [paid subscribers](https://www.axios.com/2025/08/12/gpt-5-bumpy-launch-openai)
**OpenAI's Response:**
- [Brought back GPT-4o access](https://www.tomsguide.com/ai/chatgpt-4o-is-coming-back-after-massive-gpt-5-backlash-heres-what-happened) for Plus users
- Acknowledged router problems and began [tuning improvements](https://www.axios.com/2025/08/12/gpt-5-bumpy-launch-openai)
- Added more transparency about which model responds
## Conclusion / Prediction
The router will come back - but better trained. OpenAI learned that accuracy matters more than cost savings for user satisfaction. Expect:
- **Higher-tier customers**: Will likely get manual model selection options
- **Free/basic tiers**: Will live with the router, but a much-improved version
- **Industry trend**: Other AI companies will adopt similar routing strategies as costs mount
The economics make routers inevitable, but OpenAI's rough launch showed that execution quality determines success or failure.
---
# Instruction Aware Embeddings
> Why Your Retriever is Failing and How Context Can Save It - Instruction Aware Embeddings
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/rag/instruction-aware-embeddings/
- Published: 2025-07-08
- Updated: 2026-03-14
- Tags: rag, embedding
---
# Why Your Retriever is Failing and How Context Can Save It
Imagine asking "I want to buy apple" – do you mean Apple Inc. stock, the latest iPhone, or simply fruit? Without context, your retriever may serve you the wrong results.
---
## 1. What Is the Problem in Your Retriever & Embedding?
Modern retrievers map queries and documents into high-dimensional vectors (embeddings) and rank by cosine similarity. But when a query is **ambiguous**, plain embeddings struggle:
- They collapse multiple meanings of "apple" into one vector.
- The top results can mix stock guides, product pages, and nutrition articles.
You might think this is a hypothetical scenario that rarely occurs in practice. However, here's a real-world example from Google Deep Research that illustrates the issue:
```text
Query: "We want to create a simple presentation on MCP server. We want to discuss why it's needed, current limitations, and potential use cases.
We also want to highlight its technical challenges.
Let's write a concise presentation for this."
```
It returned information about "Unisys ClearPath MCP" rather than the intended "Model Control Protocol (MCP)" proposed by Anthropic. This real-world misalignment underscores how context-less embeddings can derail retrieval.
---
## 2. Missing Context in Embedding
Embeddings encode **semantic similarity** but lack task or intent signals. Out of the box, they answer the question:
> "Which documents *sound* most like this query?"
They don't know if "apple" refers to finance, technology, or groceries—so they return a blend of all.
---
## 3. How Does It Work Without Context?
Using script's results (see [gist](https://gist.github.com/immortal3/6af71b0f9be87489d13a7e0f2cf68120)), here's the **plain embedding** behavior for "I want to buy apple" with OpenAI and Qwen models:
```text
📝 Query: 'I want to buy apple'
🔍 Using plain query (no instruction)
🤖 OpenAI Model Results:
1. How to Buy Apple Stock (Score: 0.536)
2. Where to Buy Apples (Score: 0.497)
3. iPhone 15 Pro Purchase (Score: 0.455)
🤖 Qwen Model Results:
1. Where to Buy Apples (Score: 0.604)
2. How to Buy Apple Stock (Score: 0.594)
3. Health Benefits of Apples (Score: 0.501)
```
Both embeddings mix stock, fruit, and product topics. The **Qwen** model edges out OpenAI by a small margin, but neither is decisively focused.
## 4. Introducing Qwen & Replicating the Same Thing in OpenAI
The [Qwen3-Embedding-8B model](https://qwenlm.github.io/blog/qwen3-embedding/) is **instruction-aware**, trained to accept task descriptions alongside queries. When we add a "grocery shopping" instruction:
```python
# Minimal instruction-aware query construction
instruction = "Given a grocery shopping question, retrieve fruit purchase information"
query = "I want to buy apple"
instructed_query = f"Instruction: {instruction}\nQuery: {query}"
```
---
**Visualizing the Flow:**
```text
User Query: "I want to buy apple"
|
v
[Plain Embedding Model]
|
v
Results: [Stock guides, iPhones, fruit articles] <-- Mixed, ambiguous
User Query + Instruction: "Given a grocery shopping question, retrieve fruit purchase information\nI want to buy apple"
|
v
[Instruction-Aware Embedding Model]
|
v
Results: [Fruit purchase guides, grocery info] <-- Focused, relevant
```
---
### Focused Scenario Performance Gains
Below is a comparison of similarity scores for the **correct document** in each use case, showing how instruction-aware embeddings shift the focus within the same model.
Note, OpenAI does not support instruction-aware embeddings yet, but we tried to run the same instruction-aware query with OpenAI's embedding model. As you can see, it did not work very well and it's clear, instruction-aware embeddings need to be supported by the model and it's not just a matter of adding a prefix to the query.
| Scenario | Model | Plain Score | Instruction Score | Δ Score |
|----------------------------------|--------|-------------|-------------------|-----------|
| Financial (Stock Purchase) | OpenAI | 0.536 | 0.472 | −0.064 |
| Financial (Stock Purchase) | Qwen | 0.594 | 0.743 | +0.149 |
| Technology (iPhone Purchase) | OpenAI | 0.455 | 0.393 | −0.062 |
| Technology (iPhone Purchase) | Qwen | *<0.501* | 0.512 | **↑** |
| Grocery (Fruit Purchase) | OpenAI | 0.497 | 0.502 | +0.005 |
| Grocery (Fruit Purchase) | Qwen | 0.604 | 0.680 | +0.076 |
*Note:* Qwen did not surface the iPhone doc in its top-3 plain results (score <0.501), yet it rises to #2 (0.512) with instruction.
**What does this mean?**
Notice how Qwen's instruction-aware mode dramatically increases the relevance score for the correct document, while OpenAI's model barely changes or even drops. This demonstrates that simply adding instructions to the query only works if the model is trained to use them.
---
## 5. Alternative: Query Rewriting
Embeddings also benefit when the query itself carries the necessary context. Instead of relying solely on instruction-aware models, you can rewrite the user's query using chat history or domain knowledge to inject focus. For example:
- **Original Query:** "I want to buy apple"
- **Rewritten Query:** "Where can I buy fresh apples at my local grocery store?"
Such rewrites embed context directly into the text, allowing plain embedding models to retrieve the correct documents (fruit vendors, grocery guides) without specialized instructions. This technique can be automated via:
- A chat interface that remembers previous messages and reformulates queries.
- A domain-specific rewriter that maps generic queries to more precise, vocabulary-rich versions.
By combining query rewriting with embeddings, you get the best of both worlds: minimal model changes and focused retrieval.
---
## 6. What You Can Do About It
Facing ambiguous queries? You have four straightforward strategies:
1. **Instruction-aware embeddings**
- Use models like Qwen3-Embedding-8B that accept contextual instructions.
- Best for: New projects or high-priority use cases.
- Trade-offs: Requires switching your embedding provider.
2. **Query rewriting**
- Rewrite queries to inject context (e.g., "Where can I buy fresh organic apples?").
- Best for: Legacy systems or teams using plain embedding models.
- Trade-offs: Requires building and maintaining rewriting logic.
3. **Hybrid approach**
- Combine query rewriting for immediate gains with instruction-aware models for future migrations.
- Best for: Teams seeking a phased adoption strategy.
- Trade-offs: More complex workflow but balances risk and reward.
4. **Ask clarifying questions**
- Detect vague or ambiguous queries and prompt the user for more details before retrieving.
- Best for: Interactive search interfaces and chatbots.
- Trade-offs: Requires a conversational UI and may add extra steps to user interactions.
Choose the strategy that fits your team's resources and goals, and start by tackling your most ambiguous queries first.
---
## 7. Closing Thoughts
- **Missing context** in embeddings is the core challenge for ambiguous queries.
- **Instruction-aware embeddings** (like Qwen3-Embedding-8B) deliver _stronger_ task focus, dramatically improving top-ranked results.
- You can mimic this in OpenAI by manually adding instructions, but specialized models yield bigger gains.
**What should you do next?**
- Audit your current retrieval system for ambiguous queries.
- Experiment with instruction-aware models if available.
- Implement query rewriting where needed to improve retrieval focus.
Embrace instruction-aware retrieval to resolve ambiguity and serve exactly what users intend—every time.
---
*References:*
- Qwen3 Embedding model card: [Hugging Face](https://qwenlm.github.io/blog/qwen3-embedding/)
- Code example and full script: [compare.py on GitHub Gist](https://gist.github.com/immortal3/6af71b0f9be87489d13a7e0f2cf68120)
---
# How to improve RAG retrieval: recall, precision, and NDCG
> Improve RAG retrieval without sacrificing precision: tune chunking, hybrid search, reranking, filters, and recall/NDCG metrics.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/rag/retrieval-imprv/
- Published: 2025-03-08
- Updated: 2026-06-17
- Tags: rag
---
# Improving Retrieval in RAG (via Recall, Precision, and NDCG)
## Introduction
Retrieval-Augmented Generation (RAG) is the superhero sidekick that grounds your Large Language Model (LLM) in cold, hard facts. But here's the dirty secret: if your retrieval sucks, your RAG system is just a fancy chatbot with a broken brain. Weak retrieval = missed documents, irrelevant results, and rankings that make no sense.
This guide cuts through the noise. You'll learn how to turbocharge your RAG retrieval with a no-fluff, step-by-step approach to maximize recall, sharpen precision, and nail NDCG. Whether you're a data scientist, developer, or AI enthusiast, this is your playbook to stop screwing around and start getting results. Let's roll.
## The Basics of Retrieval
### Vector Search vs. Full-Text Search
Retrieval is the backbone of RAG, and it's a tug-of-war between two heavyweights: vector search and full-text search. Here's the breakdown:
**Vector Search**: Turns words into numbers (embeddings) to capture meaning. Think of it as a genius librarian who gets that "machine learning frameworks" is related to "neural network libraries" even if the exact words don't match.
*Example*: Query = "machine learning frameworks." Vector search grabs articles about "PyTorch vs TensorFlow comparison" because it understands semantic similarity.
**Full-Text Search**: The old-school keyword matcher. It's like a librarian who only cares about exact titles—if "machine learning frameworks" isn't in the text, you're out of luck.
*Example*: Same query, "machine learning frameworks." Full-text search might miss that PyTorch article unless the phrase matches perfectly, but it'll snag anything with "frameworks" lightning-fast.
Here's a quick comparison:
| Feature | Vector Search | Full-Text Search |
|---------|--------------|------------------|
| Strengths | Semantic understanding | Speed, exact matches |
| Weaknesses | Slower, resource-hungry | Misses context |
| Best For | Complex queries | Simple lookups |
**Why Both Matter**: Hybrid search (vector + keywords) is the cheat code. Combine them, and you get the best of both worlds—broad coverage with pinpoint accuracy.
## Metrics 101 – What to Optimize For
You can't fix what you don't measure. Here's your retrieval holy trinity:
**Recall**: Are you finding all the good stuff?
*Example*: Imagine 100 blog posts about "transformer architecture" exist. Your retriever grabs 85 of them. That's 85% recall. Miss too many, and your LLM is flying blind.
**Precision**: Are you dodging the junk?
*Example*: You retrieve 100 documents for "transformer architecture," but only 70 are relevant (the rest are about "electrical transformers"). That's 70% precision. Too much noise, and your RAG drowns in garbage.
**NDCG** (Normalized Discounted Cumulative Gain): Are the best hits at the top?
*Example*: Picture the perfect ranking: top 5 results about transformer models are gold, next 5 are decent. If your retriever puts electrical engineering papers at #1 and buries the good ML content at #10, your NDCG tanks. High NDCG = happy users.
### The Hierarchy of Needs
1. **Recall First**: Cast a wide net—don't miss the critical docs.
2. **Precision Next**: Trim the fat—keep only what's relevant.
3. **NDCG Last**: Polish the rankings—put the best up top.
## Step 1 – Maximizing Recall
### Why Recall First?
If your retriever misses key documents, your generator's toast. It's like cooking a steak dinner with no steak. Recall is step one—get everything on the table.
### Tactics to Boost Recall
1. **Query Expansion**: Make your query a beast by adding synonyms or related terms.
*Example*: Query = "transformer models." Expand it to "attention mechanisms," "BERT architecture," "language model design."
*What to do*:
- Check out WordNet for traditional expansion
- Use an LLM for contextual expansion or even re-writing to multiple different queries. In production, run all these expansions in parallel and merge results.
2. **Hybrid Search**: Merge vector and keyword results like a DJ mixing tracks. Use reciprocal rank fusion (1/rank) to blend the scores.
*Example*: Query = "transformer models." Vector search finds "attention mechanism design," while full-text grabs "BERT model implementations." Fusion ranks them smartly.
*What to do*:
- Use a hybrid search engine like [Pinecone](https://www.pinecone.io/learn/hybrid-search/), [Qdrant](https://qdrant.tech/articles/hybrid-search/), or [TurboPuffer](https://turbopuffer.com/docs/hybrid)
3. **Fine-Tune Embeddings**: Generic embeddings suck for niche domains. Train on your data—say, medical literature or financial reports—for better matches.
*Example*: Fine-tune on a dataset of ML research papers. Now "transformer architecture" queries snag "multi-head attention mechanism" docs too.
*What to do*:
- Do it yourself: fine-tune [BAAI/bge-small](https://huggingface.co/BAAI/bge-small-en) on your own data and benchmark it against current embeddings
- Follow LlamaIndex's [guide on embedding fine-tuning](https://docs.llamaindex.ai/en/latest/examples/finetuning/embeddings/finetune_embedding/)
- Take inspiration from Glean, which fine-tunes embeddings for each customer ([Video](https://www.youtube.com/watch?v=jTBsWJ2TKy8))
4. **Chunking Strategy**: Break documents into bite-sized pieces. Smaller chunks (e.g., 256 tokens) catch more, but overlap them (e.g., 50 tokens) to keep context.
*Example*: An ML research paper on "transformer models" split into 500-token chunks might miss a key implementation detail. Shrink to 250 tokens with overlap, and you nab it.
*Pro Tip*:
- Depending on your embedding model and domain, benchmark chunk size and overlap to find the best balance.
## Step 2 – Precision Tuning
### Why Precision Matters
You've got a pile of docs—now ditch the trash. Precision ensures your RAG isn't wading through irrelevant sludge.
### Precision-Boosting Strategies
1. **Re-Rankers**: Run a heavy-hitter model (e.g., BERT cross-encoder) on your top 50-100 results to rescore them.
*Example*: Query = "transformer architecture." Initial retrieval grabs 100 docs, including some about "electrical power transformers." A re-ranker kicks out the electrical engineering stuff, keeping ML architecture gold.
*What to do*:
- Use Cohere's Rerank API, it's dead simple to integrate
- For brave souls, try open-source options such as [ColBERT](https://github.com/stanford-futuredata/ColBERT) and [BAAI/bge-reranker-base](https://huggingface.co/BAAI/bge-reranker-base)
2. **Metadata Filtering**: Use tags like date, category, or source to slice the fat.
*Example*: Query = "transformer models." Filter out docs older than 2020 or from non-ML domains—bam, instant precision boost.
*What to do*:
- Implement with vector databases like Pinecone, TurboPuffer, or Qdrant that support metadata filtering
3. **Thresholding**: Set a similarity cutoff (e.g., cosine > 0.5) to trash low-confidence matches.
*Example*: Query = "transformer architecture." Docs below 0.5 might be random electrical engineering content—drop 'em and keep the signal.
*What to do*:
- Configure similarity score thresholds in your vector database query APIs
## Step 3 – NDCG Optimization
### Why Ranking Matters
You've maximized recall and precision—now make sure the gold is at the top. With LLMs having finite token limits, the order of retrieval can make or break your RAG system. If your best content is buried at position #30, your LLM might never see it.
### Ranking Improvement Strategies
1. **Reranking**: Use re-rankers to filter and re-rank your results. This helps to improve both precision and NDCG.
2. **User Feedback Integration**: Capture what users actually find valuable and use it to improve your rankings.
*Example*: Users consistently reference information from the third document in your RAG answers for "transformer applications." Your system learns to boost similar documents higher for that query, dramatically improving NDCG.
*What to do*:
- **Track interactions**: Implement explicit feedback (thumbs up/down) and implicit signals (time spent, follow-up questions)
- **Build feedback loops**: Create a simple database that stores query-document pairs with user ratings
- **Implement active learning**: Prioritize collecting feedback on borderline documents where the system is uncertain
- **Curate your corpus**: Ruthlessly remove consistently low-rated documents from your vector database—this is a game-changer that most teams overlook
- **Apply immediate boosts**: For frequent queries, manually boost documents with positive feedback by 1.2-1.5x in your ranking algorithm
*Pro Tip*: Don't wait for perfect data—start with a simple "Was this helpful?" button after each RAG response, and you'll be shocked how quickly you can improve rankings with even sparse feedback.
3. **Context is King**: Leverage conversation history to supercharge your retrieval relevance.
*Example*: A user asks "What are the best frameworks?" after discussing PyTorch for 10 minutes. Without context, you might return generic framework docs. With context, you nail it with PyTorch-specific framework comparisons.
*What to do*:
- **Store conversation history**: Keep the last 3-5 exchanges in a context window
- **Question rewriting**: Use the history to expand ambiguous queries
- **Context-aware filtering**: Use topics from previous exchanges to filter metadata
*Pro Tip*: Don't just append history blindly—it creates noise. Instead, extract key entities and concepts from previous exchanges and use them to enrich your current query. For example, if discussing "transformer models for NLP tasks," extract "transformer" + "NLP" as context boosters.
### Measuring NDCG Improvement
Don't fly blind—benchmark your changes:
1. Create a test set with queries and human-judged relevance scores
2. Calculate NDCG@k (typically k=5 or k=10) before and after changes
3. Aim for at least 5-10% lift in NDCG to justify implementation costs
*Pro Tip*: Let's do some LLM math that won't make your brain explode! Focus on NDCG@k based on your document size, because your poor LLM can only eat so many tokens before it gets a tummy ache.
Here's a real-world example with numbers so simple even your coffee-deprived morning brain can handle them:
- Your average document: 10,000 tokens (that's a chatty document!)
- Your fancy GPT-4o: 128,000 token capacity (big brain energy!)
- Your context + prompt: ~3,000 tokens (the appetizer)
Now for the main course calculation:
10,000 tokens × 10 documents = 100,000 tokens
100,000 tokens + 3,000 tokens = 103,000 tokens
103,000 < 128,000... We're good! 🎉
## Conclusion: Build a Retrieval Flywheel
Here's the game plan:
1. **Hybrid Search**: Max out recall—grab everything.
2. **Re-Rankers**: Sharpen precision—ditch the junk.
3. **Contextual Ranking**: Make sure the gold is at the top.
This isn't a one-and-done deal. It's a flywheel—every tweak spins it faster. Experiment with chunk sizes, thresholds, and models. Small wins stack up to massive gains.
**Final Tip**: Don't guess—test. Try a 0.7 threshold vs. 0.9. Swap 256-token chunks for 512. Data beats dogma.
## Retrieval Cheat Sheet
| Step | Goal | Tactics |
|------|------|---------|
| 1. Recall | Grab everything | Query Expansion, Hybrid Search, Fine-Tuning, Chunking |
| 2. Precision | Ditch the junk | Re-Rankers, Metadata Filters, Thresholds |
| 3. NDCG | Perfect rankings | Reranking, User Feedback, Context |
That's it—your RAG retrieval is now a lean, mean, result-spitting machine. Go forth and dominate!
---
# AWS Bedrock Converse API: one endpoint for Claude, Llama, and Mistral
> How to call Amazon Bedrock Converse API, pass messages and inference config, and handle common model-specific validation errors.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/aws-bedrock/
- Published: 2024-06-13
- Updated: 2026-06-17
- Tags: llm, ai
---
Amazon Bedrock is a fully managed service that makes high-performing foundation models (FMs) from leading AI startups and Amazon available for your use through a unified API. You can choose from a wide range of foundation models to find the model that is best suited for your use case. Amazon Bedrock also offers a broad set of capabilities to build generative AI applications with security, privacy, and responsible AI. With Amazon Bedrock, you can easily experiment with and evaluate top foundation models for your use cases, privately customize them with your data using techniques such as fine-tuning and Retrieval Augmented Generation (RAG), and build agents that execute tasks using your enterprise systems and data sources. [1]
AWS BedRock's Converse API is a single endpoint that allows you to chat with any model. Indeed, **the single endpoint** is, I believe, the best feature of AWS BedRock. Let's visit this endpoint and see how it works.
```python
model_id = "anthropic.claude-3-sonnet-20240229-v1:0"
inference_config = {"temperature": 0.5}
additional_model_fields = {"top_k": 200}
# Send the message.
response = bedrock_client.converse(
modelId=model_id,
messages=messages,
system=system_prompts,
inferenceConfig=inference_config,
additionalModelRequestFields=additional_model_fields
)
```
By changing `model_id`, you can switch between different models.
I think AWS BedRock should have used the same standards as OpenAI's client rather than creating their own
But, hey, it's still a single endpoint. right ?...
I should be just able to switch models by changing model_id. right ?....
## Hidden Gotcha of Converse API
### Not every model is available
AWS BedRock has LLama3, Anthropic Claude, Mistral and their own Titan. But, It doesn't have OpenAI models like GPT-4/GPT-4o. This might not be a deal breaker, depending on what you are trying to achieve.
You can check the availability of models in [AWS Bedrock Models](https://docs.aws.amazon.com/bedrock/latest/userguide/models-supported.html)
### Not every model has system prompt, or multi-modality support
If you check converse API parameters, you will see that there is a parameter called `system`. This parameter is used to provide system prompt to the model. However, not every model supports system prompts. (Because they were not trained with system prompts). If you're switching between models via code using ENV/Flags/Config, you might need to handle edge cases where a system prompt is unavailable for the given `modelId`. Otherwise, It will throw an Exception. (Ideally, i think it should just give a warning)
AWS has a [nice table](https://docs.aws.amazon.com/bedrock/latest/userguide/conversation-inference.html#conversation-inference-supported-models-features) to check if given model has system prompt.
The same goes for multi-modality. If your messages include images, switching between models might not be straightforward.
### Not every model has same context window
I mean this is on you, but again good reminder.
### Advance Prompt technique like Prefilling Assistant Message
```python
# code copied from https://eugeneyan.com//writing/prompting/#prefill-claudes-responses
input = """
The SmartHome Mini is a compact smart home assistant available in black or white for
only $49.99. At just 5 inches wide, it lets you control lights, thermostats, and other
connected devices via voice or app—no matter where you place it in your home. This
affordable little hub brings convenient hands-free control to your smart devices.
Extract the , , , and from this product .
Return the extracted attributes within .
"""
messages=[
{
"role": "user",
"content": input,
},
{
"role": "assistant",
"content": "" # Prefilled response
}
]
# raise error_class(parsed_response, operation_name)
# botocore.errorfactory.ValidationException: An error occurred (ValidationException) when calling the Converse
# operation: The model that you are using requires the last turn in the conversation to be a user message. Add a
# user message to the conversation and try again.
```
If you're using advanced prompting techniques, such as Prefilling Assistant Messages [3], where you pre-populate the message with text designated as 'assistant', you need to be cautious when switching between models. Not all models are compatible with this technique and their is validation check which will raise exception.
So, Overall, We are still far away from having a unified API for all models. I will update this article if i find anything new.
## References
[1] https://docs.aws.amazon.com/bedrock/latest/userguide/what-is-bedrock.html
[2] https://docs.aws.amazon.com/bedrock/latest/userguide/conversation-inference.html#conversation-inference-supported-models-features
[3] https://eugeneyan.com//writing/prompting/#prefill-claudes-responses
---
# Database audit fields: created_at, updated_at, created_by, updated_by
> When to add created_at, updated_at, deleted_at, created_by, and updated_by columns, and whether user audit fields need foreign keys.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/essential-db-design-1/
- Published: 2024-04-17
- Updated: 2026-06-17
- Tags: database, db, design
---
# Essential Fields
Be it relational or not, every table **should** have these 5 fields:
1. created_at (default now())
2. updated_at (default now())
3. deleted_at (default null)
4. created_by (not null)
5. updated_by (not null)
> Just to be clear, every table should have these 5 fields and not must. Adding these fields have other side-effects such as bloat, performance and disk size. But, if you're having these problems, i hope you're profitable.
## Why should you include this fields ?
### Auditability
Incorporating these fields into every table significantly simplifies the auditing process. They enable you to track who created or modified an entry and when these actions occurred. It's important to note that while this doesn't provide a complete audit trail, not all tables require exhaustive audit trails. These fields deliver sufficient oversight for many applications.
### Soft Delete Capability
Utilizing the `deleted_at` field for soft deletions boosts data recovery and error correction capabilities, enabling businesses to effortlessly restore mistakenly deleted data or perform historical data analysis without relying on intricate backup systems. Additionally, you can set up a cron job to transfer data to an archive table periodically. For instance, you might move all data marked as deleted over three months ago to cold storage. This strategy helps maintain manageable table sizes by systematically archiving older records.
### Row Level Security/Permissions (RLS)
These fields might seem superfluous at first, but they are incredibly useful for controlling user access to specific rows within a table. For instance, you may want to prevent a user from updating a row that was created by someone else. By using these fields, you can define such permissions clearly and effectively. Furthermore, they enable more nuanced scenarios—for example, allowing a user to restore a deleted row only if they were the original creator, while still permitting any user to delete a row. This level of detailed control ensures both data integrity and adherence to specified access protocols.
### Avoiding Nightmares: A Cautionary Tale
Imagine you've deployed a cron job in the background designed to update certain attributes in your table based on specific business logic. It ran flawlessly during the staging tests, so you pushed it to production without further validation. But then, disaster strikes: the script modifies incorrect data. Fortunately, the updated_at and updated_by fields can come to your rescue (though not always). To identify the affected data, you can execute a query like:
```sql
SELECT * FROM items WHERE updated_at BETWEEN {script_begin} AND {script_end} AND updated_by = {script_user};
```
This allows you to pinpoint the exact entries altered during the time the script ran, providing a straightforward way to assess and rectify the unintended changes. This is a prime example of how such fields can help mitigate potential disasters, helping you manage crises more effectively.
## ORM: Django
if you're using some framework for accessing db like ORM in your codebase, it becomes easier to add these fields to your tables and helper queries. For example, I am showcasing you how to add these fields in django (python).
### 1. Create mixin class
```python
from django.db import models
from django.utils import timezone
from django.conf import settings
class AuditFieldsMixin(models.Model):
created_at = models.DateTimeField(auto_now_add=True)
updated_at = models.DateTimeField(auto_now=True)
deleted_at = models.DateTimeField(null=True, blank=True)
created_by = models.ForeignKey(settings.AUTH_USER_MODEL, related_name="%(class)s_created_by", on_delete=models.SET_NULL, null=True)
updated_by = models.ForeignKey(settings.AUTH_USER_MODEL, related_name="%(class)s_updated_by", on_delete=models.SET_NULL, null=True)
class Meta:
abstract = True
def soft_delete(self):
self.deleted_at = timezone.now()
self.save()
```
What’s going on here? We’re defining fields that automatically capture when and by whom a record was created or updated. Plus, we threw in a soft_delete method for good measure, so you can "delete" records without actually losing them.
#### Slap the Mixin on a Model
Using this mixin is as easy as pie. Just inherit from AuditFieldsMixin in your model:
```python
class Item(AuditFieldsMixin):
name = models.CharField(max_length=255)
description = models.TextField()
price = models.DecimalField(max_digits=5, decimal_places=2)
# Imagine there are other fields here too!
```
### 2. QuerySets That Ignore Deleted Stuff
You don't want your default queries pulling up deleted records, right? Let’s fix that by tweaking the model’s manager to ignore anything that’s been soft-deleted:
```python
class AuditQuerySet(models.QuerySet):
def active(self):
return self.filter(deleted_at__isnull=True)
def deleted(self):
return self.filter(deleted_at__isnull=False)
class AuditManager(models.Manager):
def get_queryset(self):
return AuditQuerySet(self.model, using=self._db).active()
class Item(AuditFieldsMixin):
objects = AuditManager()
all_objects = models.Manager() # This lets you access ALL records, even the "deleted" ones
name = models.CharField(max_length=255)
description = models.TextField()
price = models.DecimalField(max_digits=5, decimal_places=2)
# More fields, potentially
```
## Conclusion
Why do you need conclusion ? This is ain't generated by GPT. I am just a human being trying to help you.
If you have any past expirences of getting saved by some random fields, please let me know. I would be happy to learn.
Send me an email at `pate@` + `dipkumar.dev`
---
# KV cache in GPT: how it speeds up transformer inference
> A NumPy walkthrough of GPT KV caching: what keys and values are cached, how attention uses them, and why generation gets faster.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/gpt-kvcache/
- Published: 2023-02-12
- Updated: 2026-06-17
- Tags: transformer, nlp, gpt, speedup
---
The common optimization trick for speeding up transformer inference is KV caching [1][1] [2][2]. This technique is so prominent that huggingface library has `use_cache` flag is enabled by default [6][6]. A few days ago, I read an awesome blog post on [GPT in 60 Lines of NumPy][3]. So, i thought, why not extend it to use the KV cache technique? So, let’s roll up our sleeves and start working on it. Before you read further, the blog assumes you have background on transformers; if you don't, then read [this blog post][3]. It’s awesome, and you will learn a lot from it.
## Why the naive single-token approach fails
First, let’s understand a few things about GPT code.
```python
def gpt(inputs: list[int]) -> list[list[float]]:
# inputs has shape [n_seq]
# output has shape [n_seq, n_vocab]
output = # beep boop neural network magic
return output
```
We can deduce from the input-output signature that we can provide arbitrary long input and receive output of the same length, with each element of the output indicating the probability of the next token. So, I can just give a single token as input and get the probability of next token. It should just work, right ?
Modifying the code of picoGPT to just give the input of the last single token and get the probability of the next token.
```python
for _ in tqdm(range(n_tokens_to_generate), "generating"): # auto-regressive decode loop
logits = gpt2(inputs[-1:], **params, n_head=n_head) # model forward pass
next_id = np.argmax(logits[-1]) # greedy sampling
inputs = np.append(inputs, [next_id]) # append prediction to input
```
We are providing `inputs[-1:]` as input (single token) to the model. So, we are just passing a single token as input. Let's see what happens.
```markdown
the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the the
```
I didn’t work. Because the main magic is in the attention, in order to have good prediction of next tokens we need to provide all previous tokens. Although in practice, we do have limited memory and compute which forces us to provide context upto last N tokens. for example, chagpt has context upto 4096. In summary, We can’t just pass a single token and get very good prediction of next token. This makes attention have quadratic complexity.
But, if we look at the architecture of GPT, we can see that we only interact with previous tokens in the attention block, all other layers, such as the embedding layer, the feed forward layer, the layer norm, etc., don’t care about previous tokens. So, what if we can cache the input of the attention block for all previous tokens and pass it during inference? We don’t have to pass all these tokens again and again. We can just pass the last token and get the probability of the next token.
## What to cache in attention
The input of the attention block is q, k, v and mask. We can try to cache q, k, and v for all previous tokens. But, let’s think about what really matters for us. We only need k and v of the previous tokens to perform attention on the current input token because we are only passing one token as input. See the image below for a visual representation of what I mean.
```python
def attention(q, k, v, mask): # [n_q, d_k], [n_k, d_k], [n_k, d_v], [n_q, n_k] -> [n_q, d_v]
return softmax(q @ k.T / np.sqrt(q.shape[-1]) + mask) @ v
```
So, we need to calculate new_k and new_v for current input token. Append it to the existing cache and pass it to attention block for further processing.
### Updating the multi-head attention cache
```python
def mha(x, c_attn, c_proj, n_head, kvcache=None): # [n_seq, n_embd] -> [n_seq, n_embd]
# qkv projection
# when we pass kvcache, n_seq = 1. so we will compute new_q, new_k and new_v
x = linear(x, **c_attn) # [n_seq, n_embd] -> [n_seq, 3*n_embd]
# split into qkv
qkv = np.split(x, 3, axis=-1) # [n_seq, 3*n_embd] -> [3, n_seq, n_embd]
if kvcache:
# qkv
new_q, new_k, new_v = qkv # new_q, new_k, new_v = [1, n_embd]
old_k, old_v = kvcache
k = np.vstack([old_k, new_k]) # k = [n_seq, n_embd], where n_seq = prev_n_seq + 1
v = np.vstack([old_v, new_v]) # v = [n_seq, n_embd], where n_seq = prev_n_seq + 1
qkv = [new_q, k, v]
```
There is one more thing we need to take care of is causal mask. When we pass single token we would like it to attend to all previous tokens.
### Adjusting the causal mask
```python
# causal mask to hide future inputs from being attended to
if kvcache:
# when we pass kvcache, we are passing single token as input which need to attend to all previous tokens, so we create mask with all 0s
causal_mask = np.zeros((1, k.shape[0]))
else:
# create triangular causal mask
causal_mask = (1 - np.tri(x.shape[0])) * -1e10 # [n_seq, n_seq]
```
Combining all the things together, we get the following code.
### Final `mha` implementation
```python
def mha(x, c_attn, c_proj, n_head, kvcache=None): # [n_seq, n_embd] -> [n_seq, n_embd]
# qkv projection
# n_seq = 1 when we pass kvcache, so we will compute new_q, new_k and new_v
x = linear(x, **c_attn) # [n_seq, n_embd] -> [n_seq, 3*n_embd]
# split into qkv
qkv = np.split(x, 3, axis=-1) # [n_seq, 3*n_embd] -> [3, n_seq, n_embd]
if kvcache:
# qkv
new_q, new_k, new_v = qkv # new_q, new_k, new_v = [1, n_embd]
old_k, old_v = kvcache
k = np.vstack([old_k, new_k]) # k = [n_seq, n_embd], where n_seq = prev_n_seq + 1
v = np.vstack([old_v, new_v]) # v = [n_seq, n_embd], where n_seq = prev_n_seq + 1
qkv = [new_q, k, v]
current_cache = [qkv[1], qkv[2]]
# split into heads
qkv_heads = list(map(lambda x: np.split(x, n_head, axis=-1), qkv)) # [3, n_seq, n_embd] -> [n_head, 3, n_seq, n_embd/n_head]
# causal mask to hide future inputs from being attended to
if kvcache:
causal_mask = np.zeros((1, k.shape[0]))
else:
causal_mask = (1 - np.tri(x.shape[0])) * -1e10 # [n_seq, n_seq]
# perform attention over each head
out_heads = [attention(q, k, v, causal_mask) for q, k, v in zip(*qkv_heads)] # [n_head, 3, n_seq, n_embd/n_head] -> [n_head, n_seq, n_embd/n_head]
# merge heads
x = np.hstack(out_heads) # [n_head, n_seq, n_embd/n_head] -> [n_seq, n_embd]
# out projection
x = linear(x, **c_proj) # [n_seq, n_embd] -> [n_seq, n_embd]
return x, current_cache
```
We introduced minor breaking changes in output as well. We are introducing `current_cache` alongside our normal output. This is because we can use an updated cache for the next run.
We also need to change a few functions to make it work.
## Propagating the cache through the transformer
```python
def transformer_block(x, mlp, attn, ln_1, ln_2, n_head, kvcache=None): # [n_seq, n_embd] -> [n_seq, n_embd]
# multi-head causal self attention
attn_out, kvcache_updated = mha(layer_norm(x, **ln_1), **attn, n_head=n_head, kvcache=kvcache)
x = x + attn_out # [n_seq, n_embd] -> [n_seq, n_embd]
# position-wise feed forward network
x = x + ffn(layer_norm(x, **ln_2), **mlp) # [n_seq, n_embd] -> [n_seq, n_embd]
return x, kvcache_updated
```
We added `kvcache` as an input to the function and returned `kvcache_updated` as an output for each transformer block. We also need to change `transformer` function.
```python
def gpt2(inputs, wte, wpe, blocks, ln_f, n_head, kvcache = None): # [n_seq] -> [n_seq, n_vocab]
if not kvcache:
kvcache = [None]*len(blocks)
wpe_out = wpe[range(len(inputs))]
else: # cache already available, only send last token as input for predicting next token
wpe_out = wpe[[len(inputs)-1]]
inputs = [inputs[-1]]
# token + positional embeddings
x = wte[inputs] + wpe_out # [n_seq] -> [n_seq, n_embd]
# forward pass through n_layer transformer blocks
new_kvcache = []
for block, kvcache_block in zip(blocks, kvcache):
x, updated_cache = transformer_block(x, **block, n_head=n_head, kvcache=kvcache_block) # [n_seq, n_embd] -> [n_seq, n_embd]
new_kvcache.append(updated_cache) # TODO: inplace extend new cache instead of re-saving whole
# projection to vocab
x = layer_norm(x, **ln_f) # [n_seq, n_embd] -> [n_seq, n_embd]
return x @ wte.T, new_kvcache # [n_seq, n_embd] -> [n_seq, n_vocab]
```
Notice, When we have already compute `kvcache`, we only return input last token to GPT2 alongside with `kvcache`. You can also see `len(kvcache) == # number of transformer blocks`. This is because we need to update `kvcache` for attention and we have single attention in each transformer block.
And, finally, it's time to change our `generate` function to use cache. In the first iteration, we will not have `kvcache` and we will pass `kvcache=None` to `gpt2` function. In subsequent iterations, we will utilise the previously generated `kvcache`.
## Using the cache during generation
```python
kvcache = None
for _ in tqdm(range(n_tokens_to_generate), "generating"): # auto-regressive decode loop
logits, kvcache = gpt2(inputs, **params, n_head=n_head, kvcache=kvcache) # model forward pass
next_id = np.argmax(logits[-1]) # greedy sampling
inputs = np.append(inputs, [next_id]) # append prediction to input
```
This cache helps us to reduce computation for each iteration. We can see that, in first iteration, we are computing attention for all tokens in input. But, in subsequent iterations, we are only computing attention for last token. Reducing time complexity from `O(n^2)` to `O(n)`.
Finally, we can verify generate text with our previous code which didn't have caching and compare two output. Both output should be same.
## Verifying the output
In terminal
```python
>>> python gpt2_kvcache.py "Alan Turing theorized that computers would one day become"
Output:
the most powerful machines on the planet.
The computer is a machine that can perform complex calculations, and it can perform these calculations in a way that is very similar to the human brain.
```
You can see the all the code in this [pull request][4]. You can also see the code in this [repository][5].
You can see more details of calculation related to kv cache memory footprint calculation and computation time in this [blog post][1].
## References
[1]:
[2]:
[3]:
[4]:
[5]:
[6]:
1. https://kipp.ly/blog/transformer-inference-arithmetic/
2. https://lilianweng.github.io/posts/2023-01-10-inference-optimization/
3. https://jaykmody.com/blog/gpt-from-scratch/
---
# LC contest problems summary
> Solutions and hints for LeetCode biweekly and weekly contest problems, organized by contest with progressive hints.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/leetcode-contest/
- Published: 2021-11-28
- Updated: 2026-04-26
- Tags: algorithms, lc
---
### [Biweekly-66 (27th Nov, 2021)](https://leetcode.com/contest/biweekly-contest-66/)
1. [2085. Count Common Words With One Occurrence](https://leetcode.com/contest/biweekly-contest-66/problems/count-common-words-with-one-occurrence/)
Use hashmap (Counter)
2. [2086. Minimum Number of Buckets Required to Collect Rainwater from Houses](https://leetcode.com/contest/biweekly-contest-66/problems/minimum-number-of-buckets-required-to-collect-rainwater-from-houses/)"
First put the bucket at best place and the remove those covering home.
Answer is (best bucket cnt + remaining house).
Corner case: check for each house is coverable
3. [2087. Minimum Cost Homecoming of a Robot in a Grid](https://leetcode.com/contest/biweekly-contest-66/problems/minimum-cost-homecoming-of-a-robot-in-a-grid/)
djikstra will fail. why ?
Too many cells to cover (10**10). Think of something else
To reach home, which path you need to take ? (cost is non-negative)
To reach home, number of rows and number of cols changes are fixed.
4. [2088. Count Fertile Pyramids in a Land](https://leetcode.com/contest/biweekly-contest-66/problems/count-fertile-pyramids-in-a-land/)
Deconstruct pyramid into smaller part and then think to calculate how many pyramids are there
we can calculate left and right perpendiculars and then construct pyramids from them
calculate for normal and flipped version of grid
### [Weekly-269 (28th Nov, 2021)](https://leetcode.com/contest/weekly-contest-269)
1. [2089. Find Target Indices After Sorting Array](https://leetcode.com/contest/weekly-contest-269/problems/find-target-indices-after-sorting-array/)
Implementation
2. [2090. K Radius Subarray Averages](https://leetcode.com/contest/weekly-contest-269/problems/k-radius-subarray-averages/)
Prefix sum
3. [2091. Removing Minimum and Maximum From Array](https://leetcode.com/contest/weekly-contest-269/problems/removing-minimum-and-maximum-from-array/)
Greedy cases to minimize number of remove
min(r+1, n-l, l+1+(n-r)). here l and r are index of max and min elements (l < r).
4. [2092. Find All People With Secret](https://leetcode.com/contest/weekly-contest-269/problems/find-all-people-with-secret/)
sort by time and try to share secret
at current timestamp, find connected components and color all nodes if one of them have seen secret
---
# Hugo commands
> A quick reference for common Hugo static site generator commands and workflows.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/posts/hugo-cmds/
- Published: 2021-11-28
- Updated: 2026-04-26
- Tags: hugo
---
### run local server
```
hugo server -D
```
### Create New Post
```
hugo new content/posts/{post-name}.md
```
### Hugo build/export the site
```
hugo -d ../becoming-the-unbeatable
```
### relative imports
example: static\icons\favicon.png \
relative imports: icons\favicon.png
### fix for label image
icon: small_icon.jpg
instead of
icon: small_icon.png
github issue: https://github.com/adityatelange/hugo-PaperMod/issues/622
---
# Positional Encoding and RoPE
> A compact note on sinusoidal positional encoding, its key components, and how that geometry leads to RoPE.
- Author: Dipkumar Patel
- URL: https://dipkumar.dev/notes/llm/rope/
- Published: 2026-04-18
- Tags: llm, transformer, attention
---
## Sinusoidal positional encoding
Transformers do not have recurrence, so token order must be injected explicitly. The original paper does that with a fixed sinusoidal positional encoding:
```text
PE(pos, 2i) = sin(pos / 10000^(2i/d))
PE(pos, 2i+1) = cos(pos / 10000^(2i/d))
```
This looks strange at first, but the geometric intuition is simple: every pair of dimensions behaves like a tiny clock running at its own speed.
Rewrite the denominator as a frequency term:
```text
omega_i = 10000^(-2i/d)
```
Then each pair is:
```text
(sin(pos * omega_i), cos(pos * omega_i))
```
- `pos` tells us how far to move around the circle.
- `i` picks the frequency band.
- Small `i` means fast rotation.
- Large `i` means slow rotation.
The full positional vector is just many such rotating pairs concatenated together.
## Two components of sinusoidal positional encoding
The formula is easier to understand if you separate its two moving parts.
### 1. Position term
`pos` is the token position. As `pos` increases, every sinusoidal pair advances.
- Position `0` gives a fixed starting point.
- Position `1`, `2`, `3`, ... rotates each pair further.
- So `pos` controls phase.
### 2. Frequency term
The term `10000^(-2i/d)` decides how quickly each pair rotates.
- Lower-index pairs rotate quickly and capture short-range changes.
- Higher-index pairs rotate slowly and capture coarse, long-range structure.
- Using many frequencies makes positions easier to distinguish over long sequences.
There is also a structural detail worth calling out: each frequency is represented by two coordinates, `sin` and `cos`, so that one logical frequency becomes a 2D point on the unit circle.
## Tiny example
If `d = 4`, there are two pairs:
```text
PE(pos) = [
sin(pos),
cos(pos),
sin(0.01 * pos),
cos(0.01 * pos)
]
```
For positions `0`, `1`, and `2`:
```text
PE(0) = [0, 1, 0, 1]
PE(1) ~= [0.84, 0.54, 0.01, 0.99995]
PE(2) ~= [0.91, -0.42, 0.02, 0.9998]
```
The first pair changes quickly. The second barely moves. That mix of fast and slow clocks is the core idea.
## Why sine and cosine appear together
The important property is not just that sine and cosine are smooth. The useful property is that a position shift becomes a linear rotation.
For a single frequency `omega`:
```text
[ sin(omega * (p + k)) ] [ cos(omega * k) sin(omega * k) ] [ sin(omega * p) ]
[ cos(omega * (p + k)) ] = [ -sin(omega * k) cos(omega * k) ] [ cos(omega * p) ]
```
So moving from position `p` to position `p + k` is just a rotation in the 2D plane.
This is the bridge to RoPE: relative position is already hiding inside sinusoidal encoding as rotation.
## RoPE
Standard sinusoidal encoding adds position to the token embedding:
```text
x_pos = e_token + PE(pos)
```
RoPE instead applies position by rotating the query and key vectors:
```text
q' = R(pos) q
k' = R(pos) k
```
This changes the role of positional information:
- Standard sinusoidal encoding is additive.
- RoPE is multiplicative: it rotates `q` and `k`.
- Rotation preserves norm and changes direction.
- Since attention depends on query-key alignment, rotation is a natural way to encode relative offsets.
For one 2D pair `(x0, x1)` at position `p`:
```text
theta_i = base^(-2i/d)
angle = p * theta_i
x0_new = x0 * cos(angle) - x1 * sin(angle)
x1_new = x0 * sin(angle) + x1 * cos(angle)
```
RoPE does not invent a new geometry. It makes the rotation structure explicit and applies it directly where attention uses it.
## RoPE code
```python
import numpy as np
def rope_angles(seq_len: int, dim: int, base: float = 10000.0):
assert dim % 2 == 0
positions = np.arange(seq_len)[:, None] # [seq_len, 1]
freqs = base ** (-np.arange(0, dim, 2) / dim) # [dim/2]
angles = positions * freqs[None, :] # [seq_len, dim/2]
return np.cos(angles), np.sin(angles)
def rotate_half(x: np.ndarray) -> np.ndarray:
x_even = x[..., ::2]
x_odd = x[..., 1::2]
x_rot = np.stack((-x_odd, x_even), axis=-1)
return x_rot.reshape(x.shape)
def apply_rope(x: np.ndarray, cos: np.ndarray, sin: np.ndarray) -> np.ndarray:
# x: [..., seq_len, dim]
cos = np.repeat(cos, 2, axis=-1)
sin = np.repeat(sin, 2, axis=-1)
return (x * cos) + (rotate_half(x) * sin)
```
Use RoPE on `q` and `k` after projection and before attention score computation.
## References
- Vaswani et al., Attention Is All You Need: https://arxiv.org/abs/1706.03762
- Su et al., RoFormer: Enhanced Transformer with Rotary Position Embedding: https://arxiv.org/abs/2104.09864
- Hugging Face Transformers internal RoPE utilities: https://huggingface.co/docs/transformers/en/internal/rope_utils